

Industrial AI engineer and founder of Agulhas Code in Durban, South Africa: predictive maintenance, cited procedure assistants and human-supervised agents for heavy industry, each published with how it was tested and where it falls short.
Available for contract and fractional work. Durban (UTC+2), one hour behind Riyadh, so the working day overlaps almost entirely with Gulf hours.
Website · LinkedIn · Agulhas Code · darrshangovender@gmail.com
The featured repositories run offline by default with no API keys, state what their results were measured on, and list their limitations. Where the data is synthetic or the model is simulated, the README says so.
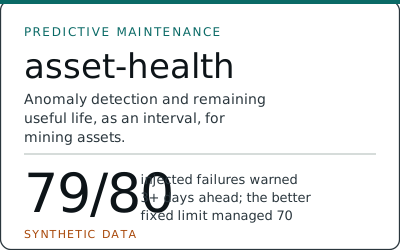
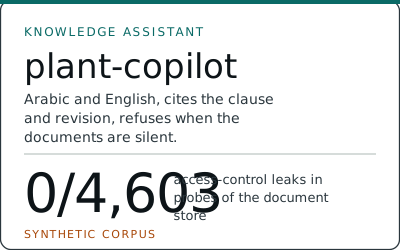
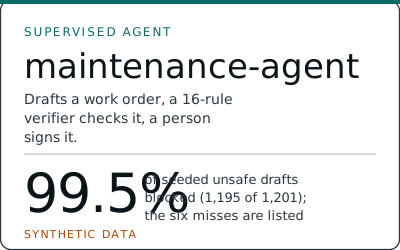
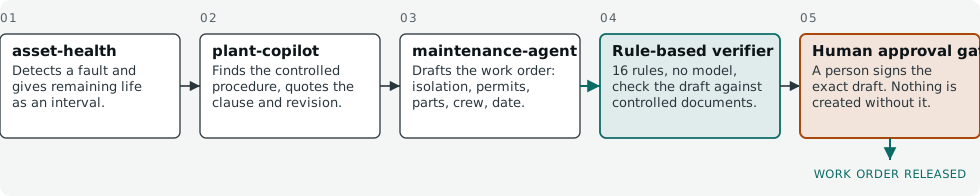
A reference flow through three separate repositories, asset-health, plant-copilot and maintenance-agent. They share no code, each runs on its own synthetic data, and maintenance-agent has not been run against the other two, so this is a design and not an integrated product. The site has architecture diagrams of each and two replays driven by the repositories' own output.
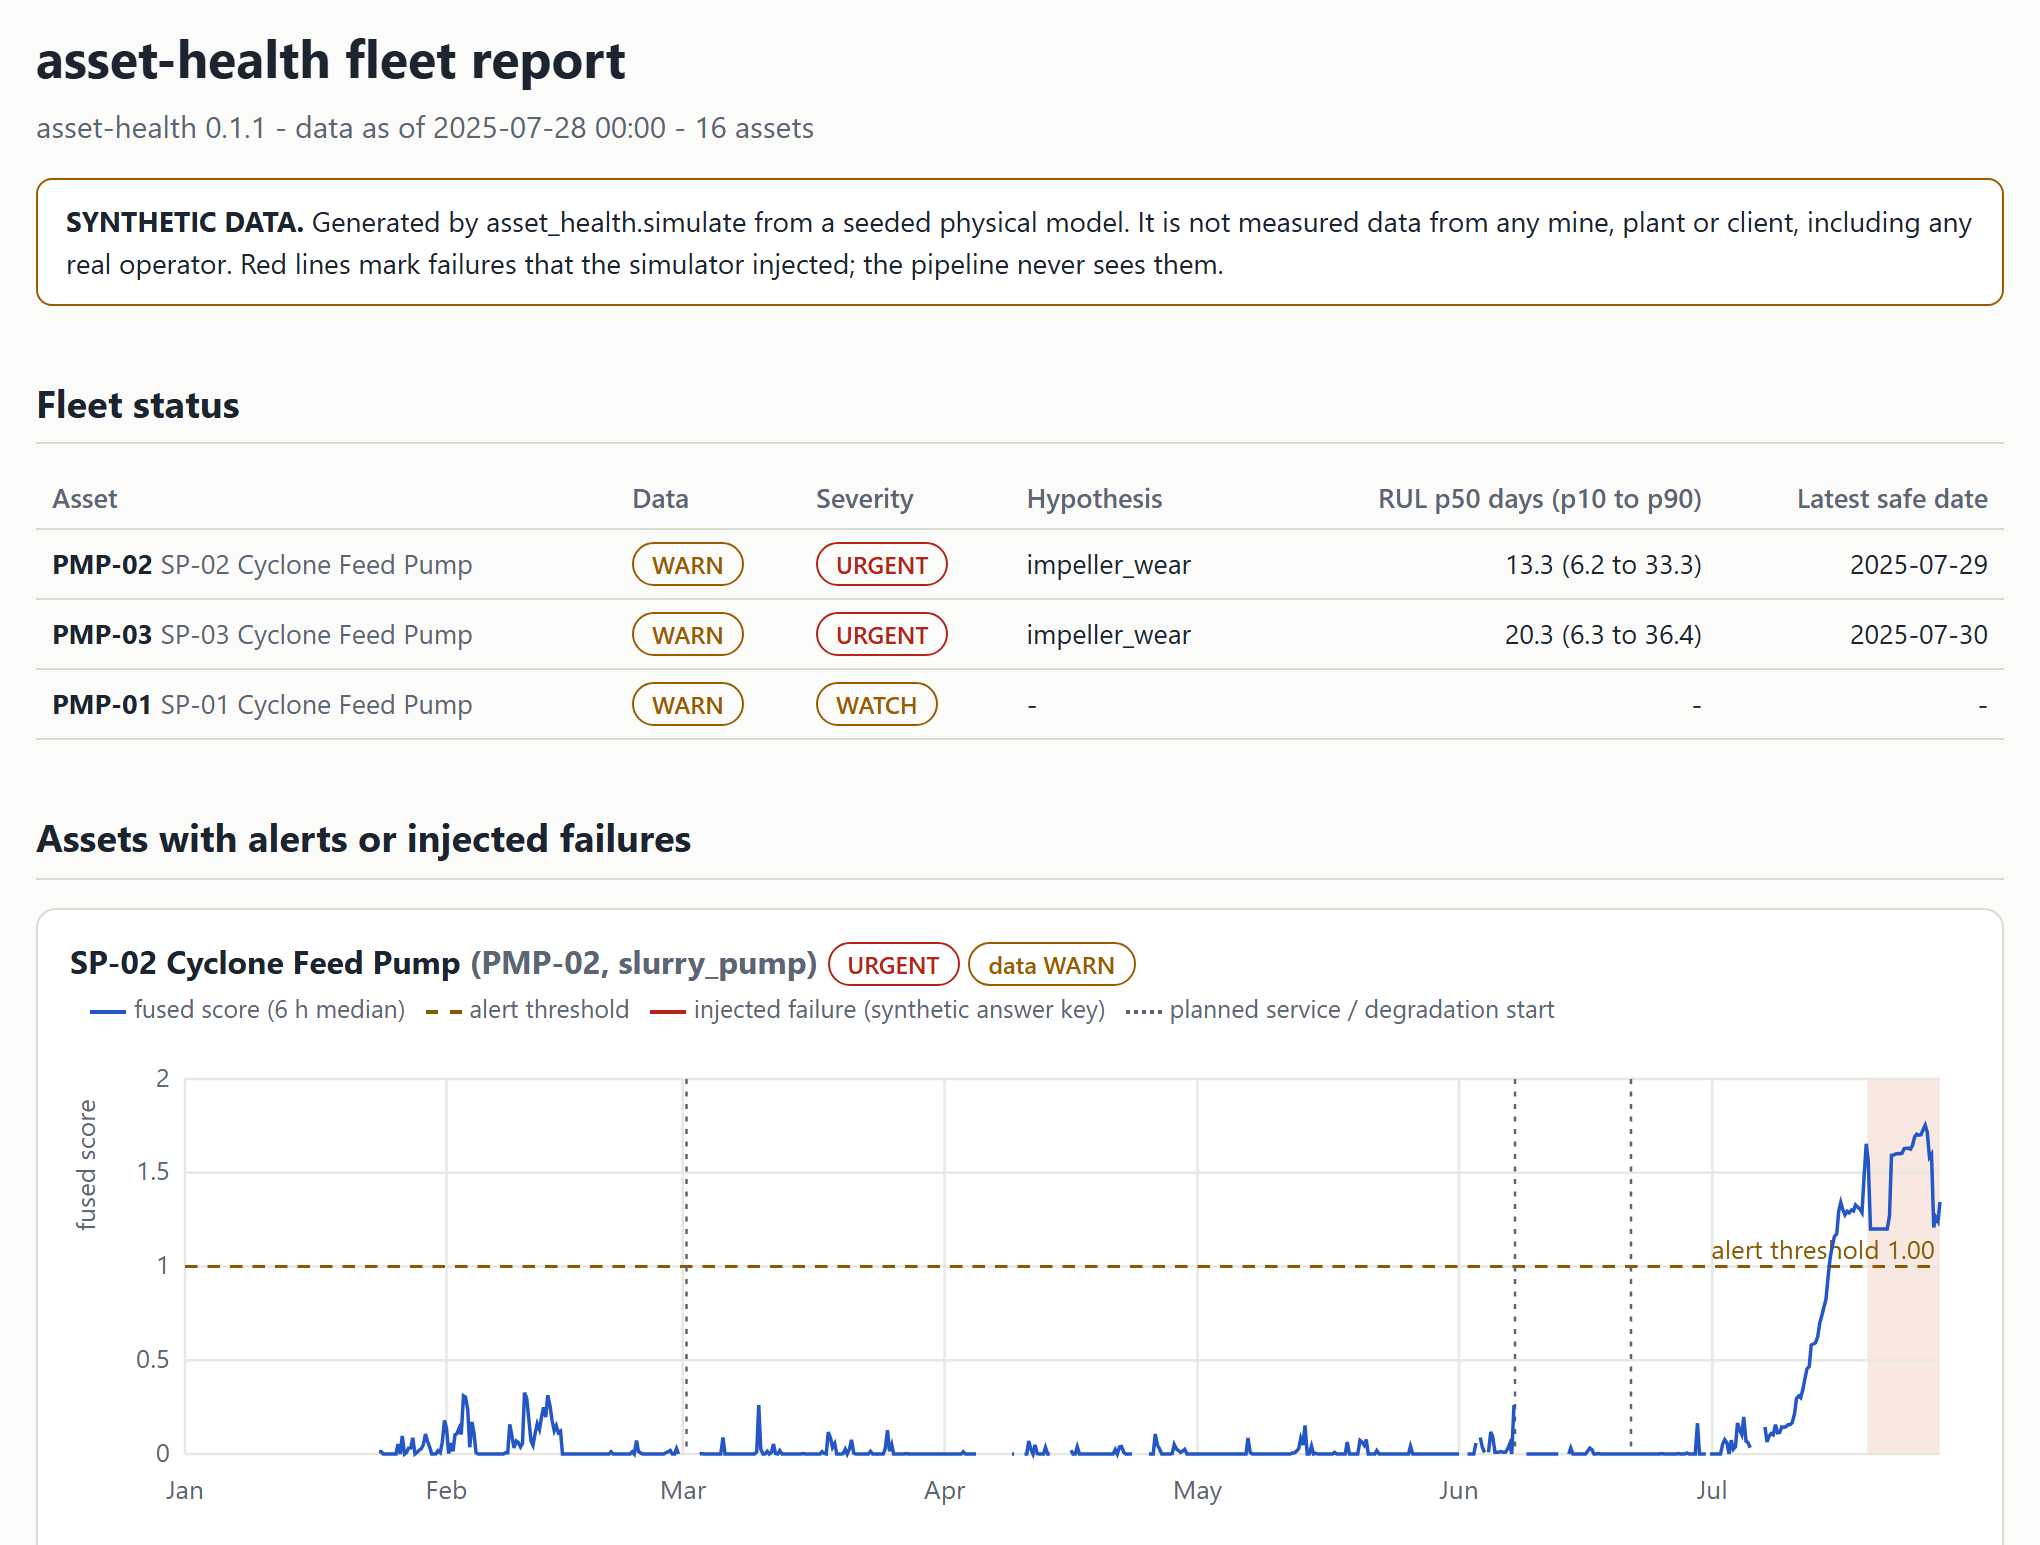
Top of asset-health's self-contained fleet report on its seeded synthetic fleet. The full report also shows the work order it drafts.
The harness runs a maintenance stack as one loop on a simulated plant, attacks it on held-out seeds under a pre-registration, and publishes its losses at the same size as its wins. Version 0.2 asks the same question of NASA's C-MAPSS turbofan trajectories, which are simulated, not field data.
- closed-loop (v0.1, synthetic data). The shield behaved as its proof predicts: 0 violations of P1 to P3 in 500 episodes for each of two hostile proposers, against 306 of 500 and 150 of 150 with it off. The thesis did not hold where it was registered: closing the loop did not move pooled coverage outside the band of 0.03 (C-PERC.pooled, a loss). A second full run matched the first on 2,962 of the 2,967 records they share.
- closed-loop-v2 (v0.2, NASA C-MAPSS, simulated). One full run, on 10 November 2026, after the freeze. V1, calibrated once, stayed inside the band when the loop closed: -0.0058 pooled over 373 evaluation units (interval -0.0255 to 0.0143), a loss for the thesis. V2L, which learns from the lives the policy ends, lost coverage: -0.0767 pooled (interval -0.0864 to -0.0670), a win for the thesis.
The limits are in each repository's own README: one author, simulated data, and a proof that covers a finite abstraction and safety, not progress.
Cost, safety and reliability controls that sit around a model.
| Repository | What it does | Key result |
|---|---|---|
| cascade | Verifier-gated model cascade: answer with the cheapest model first, escalate only when verification fails, fit the thresholds offline. Benchmarked on a simulated model. | Counts every verifier call, priced from the list prices in the repo. On the simulated benchmark a 2-tier cascade is 5% cheaper at 99% of the strong model's accuracy; the 3-tier one costs more, and the README shows why. |
| context-compress | Prompt and RAG context compression with a fact-recall evaluator, so savings are reported next to what was lost. | On a synthetic RAG set: 48% fewer tokens with every fact kept, where naive truncation saves 57% but keeps 21.7%. |
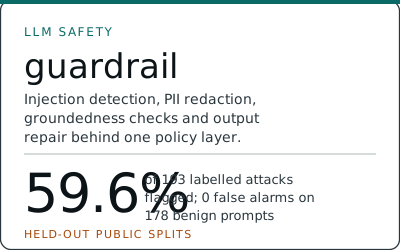
| guardrail | Safety gateway for model inputs and outputs: prompt-injection detection, PII redaction, groundedness checks and structured-output repair behind one policy layer. | On the held-out test splits of two public datasets (whose training splits informed its patterns): 59.6% of 193 labelled attacks flagged, 0 false alarms on 178 benign prompts. Saudi National ID/Iqama, IBAN and mobile detection with checksums. |
| sql-guardrails | Makes LLM-written SQL safe to execute: sqlglot AST allowlisting, read-only enforcement and optional EXPLAIN cost limits. Ships an adversarial corpus. | Executes only the guard's own normalised SQL, so a parser disagreement between guard and database cannot become a bypass. 22 functions blocked permanently, beyond the reach of config. |
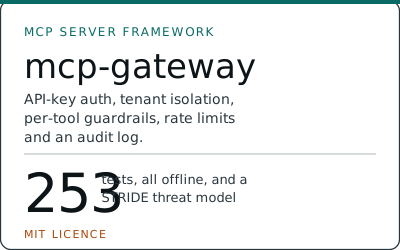
| mcp-gateway | MCP server wrapper with API-key auth, tenant isolation, per-tool guardrails, rate limits and an audit log. Serves the 2026-07-28 MCP revision and the 2025 revisions side by side. | STRIDE threat model; 253 tests |
| agent-runtime | Checkpointed state-machine executor for agents: resume after a crash, identical-call loop breaker, model fallback chain, schema self-correction. | Design reference; no headline number |
| thinking-loop | Published test-time reasoning strategies behind one interface, adjudicated by a critic, under hard token, time and cost budgets. | Benchmark harness; a real-model run needs your own key |
| rag-eval-harness | Faithfulness, answer relevance and recall@k for RAG pipelines, wired into CI so a regression fails the build. | A CI gate, not a benchmark |
- lease-abstract: South African residential lease abstraction with per-field clause citations and compliance checks against the Rental Housing Act and the Consumer Protection Act.
- affordability-scorer: explainable tenant affordability scoring with tamper detection, calibration and structural fairness checks. No LLM in the scoring path.
- whatsapp-agent-kit: WhatsApp Business agents with webhook dedup, the session window rule, human handoff and POPIA-aware redaction. Runs offline against a mock transport.
Also: multi-agent-orchestrator · rag-graph · rag-chatbot · doc-intelligence · insightengine · agent-tool-router · semantic-cache · llm-cost-tracker · prompt-versioner · prompt-eval-toolkit · lead-scorer · churn-forecasting · recommendation-engine
- Offline by default. Tests, examples and benchmarks need no API keys and no network. Hosted-model paths are optional extras, so data can stay inside the client environment.
- Every number has a script. Results are regenerated by a script in the repository and say what they were measured on: synthetic data, a simulated model, or a bundled corpus.
- Controls sit outside the model. Rule-based verifiers, AST allowlists, access control before retrieval and human approval gates, not instructions in a prompt.
- Limitations are written down. Each README has a Limitations section that says what changes on real data.
Available for contract and fractional work. I am in Durban (UTC+2), one hour behind Riyadh, so the working day overlaps almost entirely with Gulf hours.
darrshangovender.github.io · LinkedIn · agulhascode.co.za · darrshangovender@gmail.com