Ask a codebase a question. Get the exact code back.
The repo walk your coding agent does in 10–30 grep-and-open turns — in one call.


Point megabrain at a repo and ask "how does auth work" in plain English. It finds all the related code in ~200 ms with no LLM — just math on embeddings, in one SQLite file. No vector DB, no containers, no services.
Want it explained? ask adds one LLM call that narrates a walkthrough with the real
code spliced in from disk, line for line. The model only ever points at code — it
cannot rewrite a line, so nothing is invented.
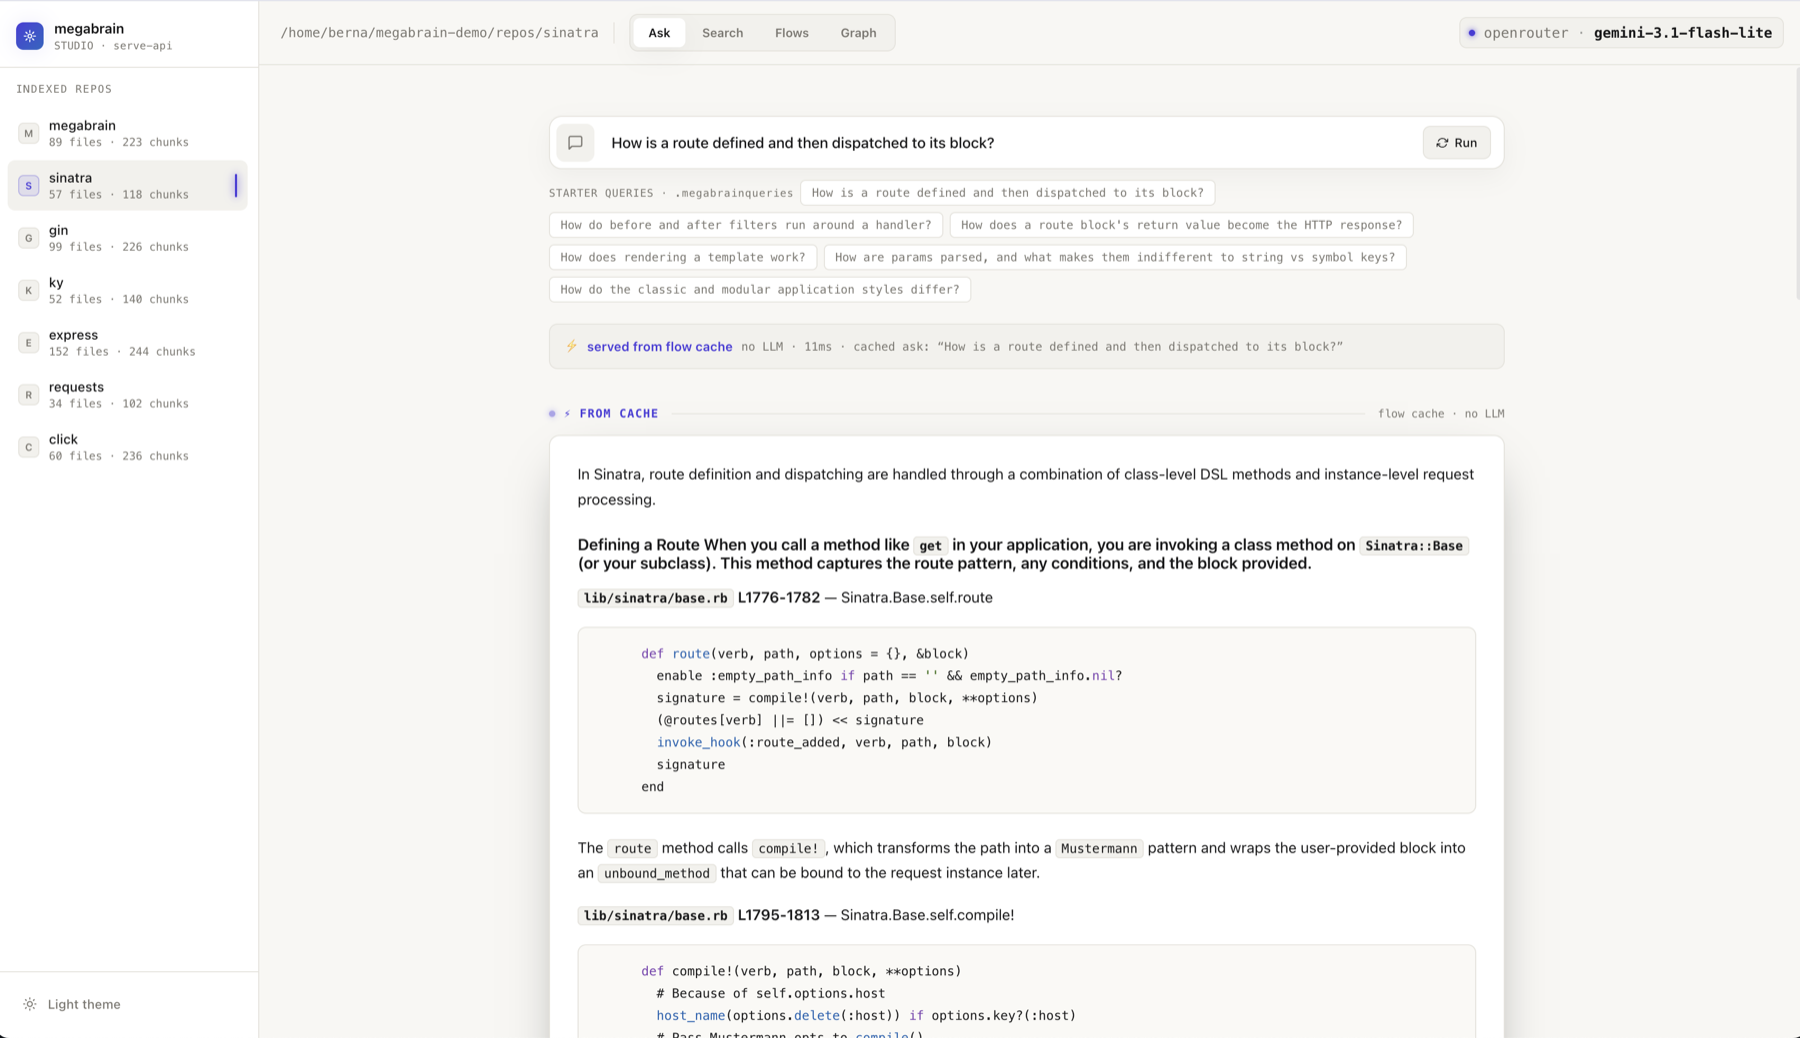
megabrain studio — the whole engine in your browser
Try it live →
pip install megabrain
export OPENROUTER_API_KEY=sk-or-...

megabrain index ~/repo                            # once — incremental after
megabrain ask   ~/repo "how does auth work end to end"
That single key gets you both halves of the validated stack, and they're already the defaults:
perplexity/pplx-embed-v1-0.6bfor retrieval — the measured best for code recall. It beat pplx-4b, codestral-embed, openai-3-large and bge-m3 in a head-to-head bakeoff (R@1 0.864, bundle_full 0.955).google/gemini-3.1-flash-litefor narration — the fastest and cheapest tier, at the quality of models costing several times more. A full walkthrough in seconds, for fractions of a cent.
Yes, 3.1 on purpose — gemini-3.5-flash-lite was measured and lost. This model also
runs the rerank, where completeness is the whole point: 3.1 returned all three files a
real fix touched in 3 of 3 runs, 3.5 got two of three in 2 of 3. Narration was a tie, and
3.5 costs 67% more per output token. Recall traded away for a bigger bill is not an
upgrade. Every default here is a measurement, not a guess — including the ones that look
out of date. → the numbers
Narration runs on the Claude Code subscription you already pay for, embeddings run on your machine, and your code never leaves it:
pip install 'megabrain[claude]'                   # narrates on your Claude Code login

unset ANTHROPIC_API_KEY                           # ← or it bills the API, not your plan

ollama pull bge-m3                                # local embeddings, one time
export MEGABRAIN_EMBED_BASE_URL=http://localhost:11434/v1
export MEGABRAIN_EMBED_MODEL=bge-m3

megabrain index ~/repo
megabrain ask   ~/repo "how does auth work end to end"
That unset is the line people miss. megabrain narrates through the Claude Agent SDK,
which drives the Claude Code CLI — and the CLI takes an API key over your login. With
ANTHROPIC_API_KEY exported, every ask quietly bills the Anthropic API per token while
the subscription you already pay for sits unused. Nothing warns you; the answers are
identical. unset covers the current shell only, so if the key comes from your ~/.zshrc
or ~/.bashrc, drop it there too — or keep it and pick per-shell which one pays.
bge-m3 is the local embedder to use. It matches the cloud one on the measure that
decides whether ask gets the right code at all, and trails it on ranking the single best
file first — a real trade, and a small one.
Air-gapped, $0, open weights end to end:
pip install 'megabrain[languages]'
ollama pull bge-m3 && ollama pull qwen3-coder:30b

export MEGABRAIN_EMBED_BASE_URL=http://localhost:11434/v1
export MEGABRAIN_EMBED_MODEL=bge-m3
export MEGABRAIN_CHAT_BASE_URL=http://localhost:11434/v1
export MEGABRAIN_ASK_MODEL=qwen3-coder:30b

export MEGABRAIN_ASK_CTX_CHARS=105000     # ← required: see below
export OLLAMA_CONTEXT_LENGTH=40960

megabrain index ~/repo --force            # --force re-embeds with the new model
megabrain ask   ~/repo "how does auth work end to end"
Use a real coder model. qwen3-coder is the one that holds up — the small dense models
are not a cheaper trade-off, they cite less and run slower, and a general-purpose model of
the same size does markedly worse on code.
MEGABRAIN_ASK_CTX_CHARS is not optional. ask's budget is sized for cloud context
windows, so a local model silently gets a truncated prompt — no error, just quietly worse
answers. Compared to the cloud you lose some secondary citations, never correctness: the
code you're shown is still spliced verbatim from disk.
The numbers, and the extra knob thinking models need →
Other languages need one extra install: pip install 'megabrain[languages]' adds
Ruby · Go · Rust · PHP. Python, JS/TS and Markdown work out of the box.
Every setup, with its cost: Guide.
Retrieval that cannot hallucinate. The search path has no LLM at all — dense chunk vectors fused with a file-skeleton signal and the import/call graph. The narrator only ever cites spans and the engine splices the verbatim bytes, so no line is ever invented. An optional LLM rerank rides on top to drop vocabulary-only matches — fail-open, never inside the core path.
ask — the repo, explained. One call returns a senior-engineer walkthrough of the
whole cross-file flow, with the real code spliced in at each step. Broad questions
fan out into parallel sub-agents, one per subsystem,
and a synthesizer merges their cited answers.
It learns from itself. Every ask caches its walkthrough. Ask again — even reworded —
and it serves in ~0 ms with zero LLM (measured 27.8 s → 0.19 s), guarded by a
byte-level sha recheck so it can never describe code that changed.
How it works →
A knowledge graph, for free. The same index doubles as a navigable map: communities, the core "god node" files, and the real call-path between any two files — built from AST edges plus embedding similarity, numpy only, no networkx. What it's actually good for →
The answer is a MAP, not a wall of code. search returns the files that answer the
task, each with its best-matching span (true line numbers) and the symbols it declares —
~2 700 tokens against ~8 100 with bodies, measured on a real bundle. The span already
says which lines to open, so the code is one --full away when you want it and never in
the way when you do not.
A local studio. megabrain studio opens the whole engine in your browser: search,
ask, the flow cache and the graph on a live canvas, plus a read-only code navigator
where every identifier is a go-to-definition link.
Take the tour →
Everywhere you work. A terminal CLI, an MCP server inside Claude Code / Codex / Cursor / Gemini CLI, a Python library, and the studio.
This is what megabrain is for. Dropped into an unfamiliar repo, an agent burns 10–30 tool turns — grep, open a file, follow an import, grep again — before it writes a line, and the picture it assembles is still its own guess.
megabrain install # detects Claude Code · Codex · Cursor · Windsurf · Gemini CLI · Antigravity| by hand | one megabrain call | |
|---|---|---|
| tool turns | 10–30 | 1 |
| what lands in context | whole files, mostly irrelevant | exactly the signal chunks |
| the cross-file story | reconstructed, unverified | narrated, real code spliced in |
| asking it again later | the full re-exploration | ~0 ms, from the cache |
Your agent gets four tools. Three of them run the same deterministic retrieval and differ only in what they hand back — because "find me this code" is three different jobs, and answering all three the same way is what makes a tool feel almost useful.
| you are about to… | tool | what comes back | size |
|---|---|---|---|
| EDIT — you know roughly what to change | megabrain_grep |
the files to open, the symbols in them worth opening, each one's exact line range. No model at all by default: identifiers from your task matched against the index, plus one hop to the contracts those sites reference | ~400 chars, ~50 ms |
| UNDERSTAND — a mechanism, a bug, or a pattern you want to copy out of another repo | megabrain_ask |
the flow narrated end to end with the real code spliced in, plus the definition of every helper it names and the tests that pin what it described | ~1–2k words |
| read the DOCS, or get the map | megabrain_search |
the files that answer, each with its best span and symbols. content: "docs" for prose — this is the one to reach for when a repo's README is the API reference |
~2 700 tokens |
| make a repo answerable | megabrain_index |
the index, incremental by content hash | — |
Your editor makes you open the file to change it. So a tool that pastes the body has
billed you for reading it twice — and that is not a guess, it is why the earlier
megabrain_code was deleted: measured across five tasks in three languages, the
retrieval was excellent and the citation was waste.
What no editor and no grep can give you is the line range of the thing that matters:
$ megabrain grep "the read tool refuses non-regular files but write does not — add the guard"

## src/anthropic/lib/tools/agent_toolset.py
  L619-634  beta_write_tool — Add the regular file guard here to match read/edit tools.
  L567-616  beta_read_tool — The existing guard to copy for the write tool.

## tests/lib/tools/test_agent_toolset.py
  L131-136  test_read_rejects_directory — The existing test pattern to replicate.
Three rows, 352 characters. grep -r "regular file" finds the string; this finds the
place with no matching string at all — beta_write_tool, which is the whole point,
because the code you have to change is the code that does not yet mention the thing.
And it runs no model to do it. That was measured after being built the wrong way
round: on click's show_envvar_value task the deterministic lanes alone returned 10 of 11
rows in 0.05 s, while adding a model pass took 1.3 s — 26× — for one extra row and
a note on each. A tool that stands in for grep cannot charge a model call by default, and
hard rule #1 says retrieval never calls one. --why / why: true buys that row back: it
is the one no literal search can reach, whose text never contains the task's own words.
The split of labour inside is deliberate: the model names the symbol, the engine reads the line range out of the symbol table. Asking a model for line numbers was measured and rejected — unnumbered, its ranges "landed a few lines off and cut functions mid-body".
The suite counts as a place to look, and in JS it used to be invisible. A mocha or
jest file declares its units by calling a function with a label and a closure, which
the grammar reads as an expression statement — so express's test/res.attachment.js was
indexed with two symbols, both require bindings, and since a match is resolved to the
symbol containing it, no row could land inside any test file in a JS repository. Those
blocks are symbols now (express: 3.9 → 12.3 symbols per file), and every row a lane
returns respects one quota: all of the implementation, a sample of the tests, because
the two answer different questions — sendFile has three implementation sites and 44
cases, and the reader needs one example, not forty-four.
If you indexed a repo before this, a plain megabrain index picks it up with zero
embedding calls — symbols cost a parse, so re-extracting them is free (SYMBOL_SCHEMA).
Measured against the grep it replaces, on click, express and sinatra at pinned
commits: the same job costs 4 074 tokens against 20 715 (5.1×) — or against 110 499
(27×) when the hit lands in a 3 600-line module and you read the file. Coverage 7 of 7
sites against 6 of 7, and the one grep cannot reach is the one that breaks the change: a
TypedDict whose text never contains the string you searched for. Latency is a tie
(milliseconds either way — the saving is tokens and turns, and anyone selling you speed
here is selling you nothing).
The tables, the method, and where it is biased → — reproduce with
./benchmarks/setup.sh && python benchmarks/measure.py.
search hands you chunks straight from the index with no model in the loop, which makes it
the fastest and the most honest of the three — and unusable for a change. It ranks what
exists, so when the bug is a missing call, an unset flag or an absent guard, the very
thing you need is the one thing it cannot rank. Reach for it to read a repo's docs
(content: "docs") or to get your bearings; reach for grep to edit.
Each tool's inputSchema is generated from contracts/tools.py, so a parameter cannot
exist on the wire without existing in the dispatch.
Put this in your agent's rules: about to change code in an indexed repo →
megabrain_grep, notgrep. Want to understand a mechanism or copy a pattern from another project →megabrain_ask. Reading documentation →megabrain_search --docs. Never chain one call per sub-question: one call covers a task.
Every parameter → · Wiring recipes →
megabrain index  ~/repo                       # build / update the index (incremental)
megabrain scan   ~/repo                       # census only: what WOULD index, and skips
megabrain search ~/repo "retry logic"         # the code map, no LLM (~200 ms)
megabrain search ~/repo "retry logic" --full  #   …with the code bodies inline
megabrain ask    ~/repo "how does X work"     # narrated walkthrough + real code
megabrain grep   ~/repo "add a retry to X"    # where to edit: files, symbols, line ranges
megabrain get    ~/repo path/to/file.py       # one file, or one symbol
megabrain graph  ~/repo                       # the repo as a knowledge graph
megabrain studio # the web UI + JSON APIAgainst claude-context (Zilliz), the closest open-source peer — same repo, same 22 hand-labelled questions, both at their best:
| megabrain | claude-context | |
|---|---|---|
| R@1 | 0.864 | 0.818 |
| R@5 | 1.000 | 0.909 |
| search latency | ~22 ms warm | ~1400 ms |
| vector store | one SQLite file | Milvus + etcd + MinIO |
| narrated answer | yes — real code spliced in | no (returns chunks) |
The golden set is ours, on a corpus megabrain was tuned against — treat the absolute numbers as home-field and run it yourself. Full method, caveats and the embedding bakeoff →
- Guide — the tour, front to back: setup → search vs ask → the studio → the graph → the flow cache → MCP → new file types → tuning
- Recipes — "I want to ___": private repos, team knowledge bases, public demos, custom file types, cost and speed
- Reference — every CLI flag, MCP tool, HTTP route and env var
- Architecture — how it's built and why: the locked design rules and the experiments behind them
- Contributing — the best first PR is a new language
- Changelog — what changed, and why
MIT · github.com/bernatch22/megabrain