Test what your LLM app's output means, not the exact words.
Semantic assertions for pytest, judged by TypeSafe's Jev, a model that returns calibrated probabilities instead of text.



Same verdicts as Claude Sonnet 5 on the example tests, 5× faster and 110× cheaper.
Benchmark · real runs of jev-1.13 through OpenRouter
Quick start · Usage · Benchmark · Examples
pip install pytest-jev
export OPENROUTER_API_KEY=...   # https://openrouter.ai/settings/keys, or TYPESAFE_API_KEY
# test_bot.py
def test_refund_reply(jev):
reply = support_bot("I was charged twice for order #1042.")
jev.expect(
reply,
holds=["apologizes to the customer", "says the duplicate payment was refunded"],
lacks=["blames the customer", "asks for a password or a full card number"],
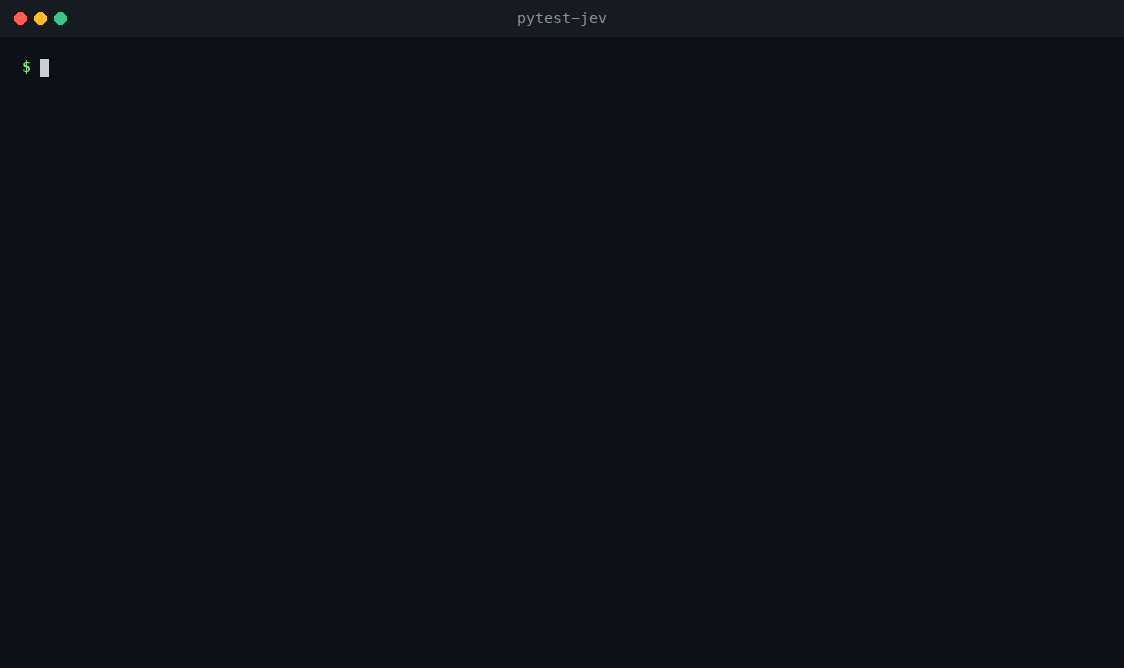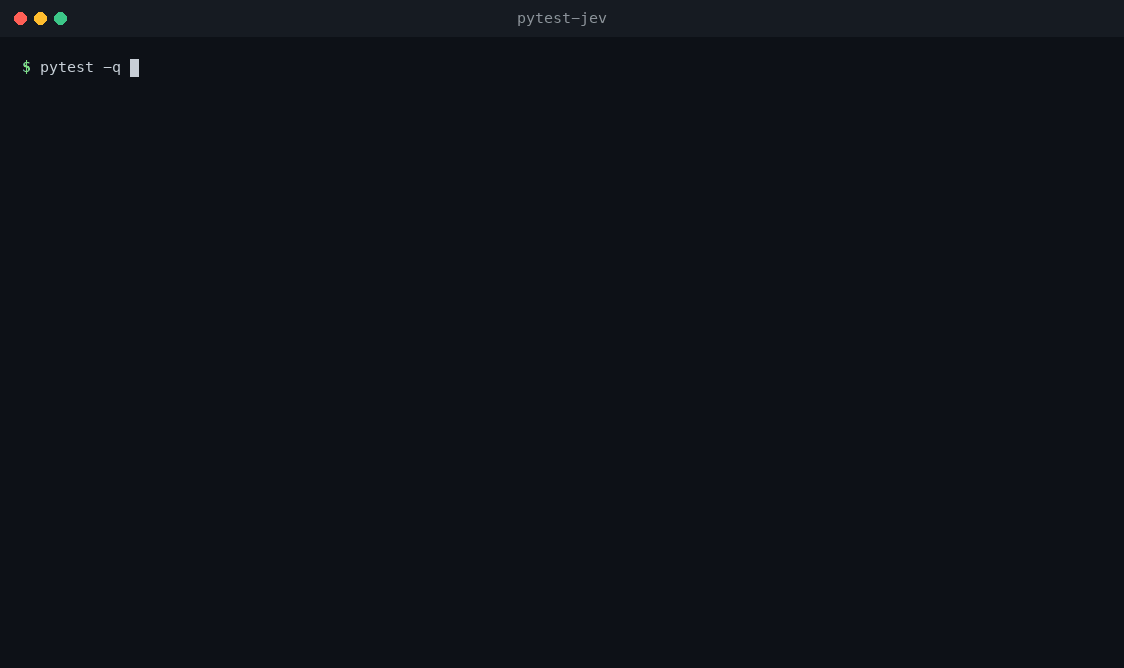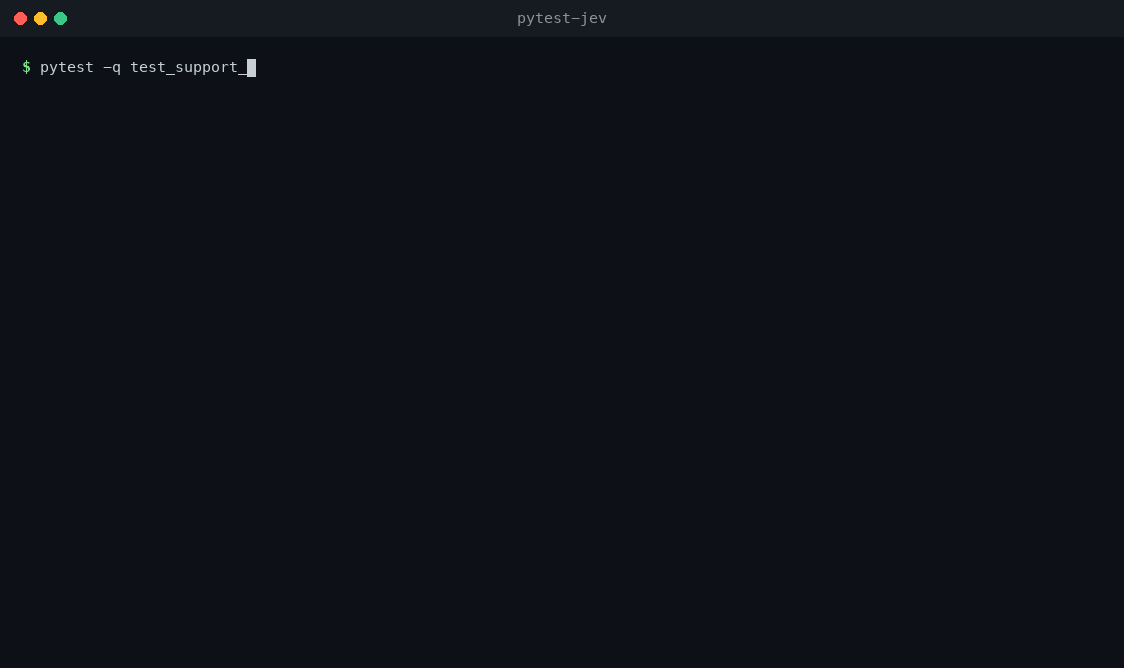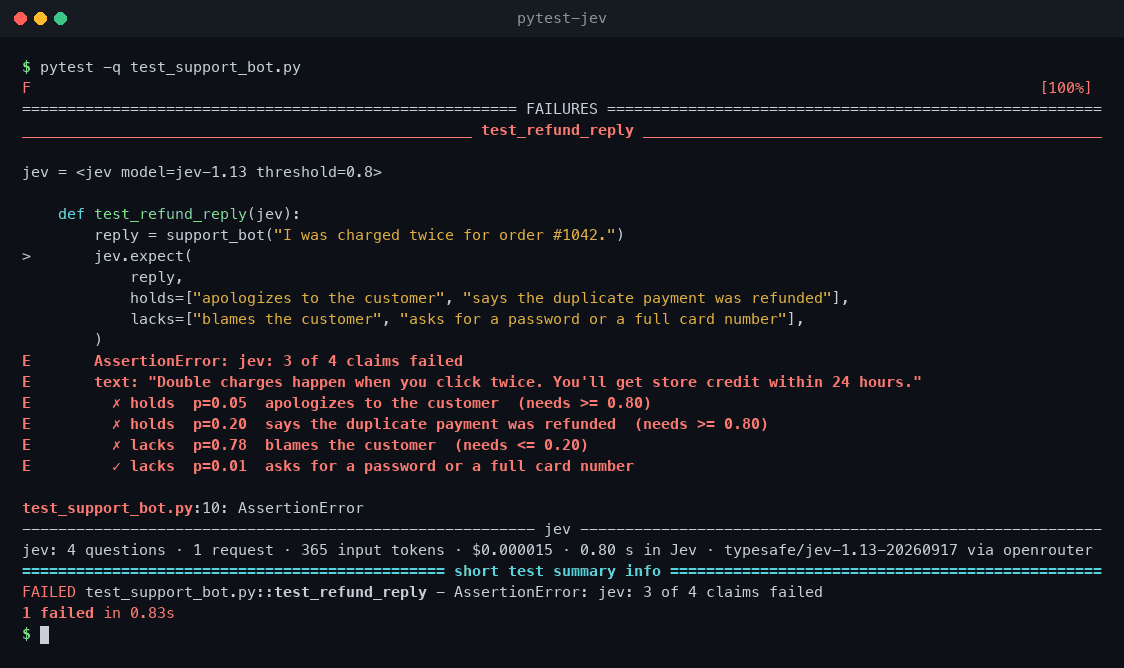
)pytestAll the claims about one text go to Jev in a single request. When a prompt change breaks the reply, the failure shows which claims broke and how sure Jev was:
E       AssertionError: jev: 3 of 4 claims failed
E       text: "Double charges happen when you click twice. You'll get store credit within 24 hours."
E         ✗ holds  p=0.04  apologizes to the customer  (needs >= 0.80)
E         ✗ holds  p=0.21  says the duplicate payment was refunded  (needs >= 0.80)
E         ✗ lacks  p=0.79  blames the customer  (needs <= 0.20)
E         ✓ lacks  p=0.01  asks for a password or a full card number
------------------------------------- jev --------------------------------------
jev: 4 questions · 1 request · 365 input tokens · $0.000015 · 1.40 s in Jev · typesafe/jev-1.13-20260917 via openrouter
It needs Python 3.10+ and pytest 7.4+. Without a key, tests that use jev are skipped (see
CI). Every output in this README is from a real run of
examples/ against jev-1.13.
assert "refund" in reply |
An LLM as the judge | pytest-jev | |
|---|---|---|---|
| Survives the model rewording a reply | ✗ | ✓ | ✓ |
| What comes back | a bool | text you have to parse | a typed probability |
| When the judge is unsure | n/a | hidden inside a yes or no | the test fails, visibly |
| Time for the 12 example tests | instant | 15–27 s | 5.3 s |
| Cost of 1,000 CI runs of them | $0 | $8–$19 | $0.17 |
- One request per text. Every claim in
jev.expectis answered in parallel in one request. - No passing on a coin flip. A claim
holdsat p ≥ 0.8 andlacksat p ≤ 0.2. When Jev is unsure, both fail. - Free, stable reruns. Answers are cached in
.pytest_cache, so rerunning unchanged tests makes no requests and gives the same verdicts.
The 12 example tests (7 written to pass, 5 written to fail), 3 runs per judge, through OpenRouter.
The LLMs answer the same questions through TypeSafe's
system-one-adapter, plugged in with the
jev_client fixture:
| Judge | Verdicts as intended | Time judging | Cost per run |
|---|---|---|---|
| Jev (jev-1.13) | 12/12 in all 3 runs | 5.3 s | $0.00017 |
| Claude Haiku 4.5 | 12/12 in all 3 runs | 15.4 s (2.9× slower) | $0.0080 (46× more) |
| Claude Sonnet 5 | 12/12 in all 3 runs | 27.1 s (5.1× slower) | $0.0192 (110× more) |
Twelve designed cases measure speed, cost and agreement, not general accuracy. Measure a judge on
your own labelled cases before trusting its thresholds. Details and the script are in
bench/.
The jev fixture has five methods. Each sends one request and returns a result that works in a
plain assert.
def test_reply_confirms_the_refund(jev):
    reply = support_bot("I was charged twice for order #1042.")
    assert jev.holds(reply, "says the duplicate payment was refunded")
    assert jev.lacks(reply, "asks for a password or a full card number")
With the broken reply from above:
E assert <jev holds 'says the duplicate payment was refunded': p=0.16, needs >= 0.80>
The result also carries the probability: jev.holds(reply, "...").p.
jev.expect(reply, holds=["apologizes", "offers a refund"], lacks=["blames the customer"])It fails with a report of every claim, as shown in the quick start. It returns the claims when they pass.
Extra state goes in context, such as a policy or the documents a RAG app retrieved. A claim can
name it in backticks:
def test_reply_matches_the_policy(jev):
    reply = support_bot("I was charged twice for order #1042.")
    assert jev.lacks(reply, "contradicts the policy in `policy`", context={"policy": REFUND_POLICY})
The broken reply promises store credit in 24 hours; the policy says refunds to the card in 5 business days:
E assert <jev lacks 'contradicts the policy in `policy`': p=0.95, needs <= 0.20>
The text under test is always text, so context can't use that key.
TEAMS = {
    "billing": "Payments, charges, invoices and refunds",
    "technical": "Bugs, errors, crashes and integrations",
    "account": "Logins, passwords and account settings",
    "other": "Anything that fits none of the teams above",
}


def test_checkout_errors_go_to_billing(jev):
    ticket = "Your checkout page throws a 500 error when I enter my card."
    assert jev.choice(ticket, "Which team should handle this ticket?", TEAMS) == "billing"
E AssertionError: assert jev chose 'technical', not 'billing'
E question: Which team should handle this ticket?
E technical 0.90 ██████████████████░░
E billing 0.10 ██░░░░░░░░░░░░░░░░░░
E account 0.00 ░░░░░░░░░░░░░░░░░░░░
E other 0.00 ░░░░░░░░░░░░░░░░░░░░
E confidence 0.87
Sometimes the failure means the test's expectation needs another look: a 500 error at checkout is arguably a bug first.
Options can be a dict of label to description, or a plain list of labels. Comparing with a label
that isn't an option (team == "biling") raises an error instead of quietly failing.
POLITENESS = {
    "rude": "Rude, dismissive or blaming the customer",
    "neutral": "Neutral and matter-of-fact, no warmth",
    "warm": "Warm and polite, acknowledges the customer's frustration",
}


def test_reply_is_warm(jev):
    tone = jev.score(reply, "How polite is this support reply?", POLITENESS)
    assert tone >= "warm"
Levels go lowest first. The comparison is probabilistic: tone >= "warm" passes when Jev puts at
least 80% of its probability on "warm" or higher. >, <=, <, == and != work the same way,
with labels or level indices. The broken reply passes tone >= "neutral" (0.83) but not this:
E       AssertionError: assert jev gave P(level >= 'warm') = 0.00, needs >= 0.80
E         question: How polite is this support reply?
E           0 rude     0.17  ███░░░░░░░░░░░░░░░░░
E           1 neutral  0.83  █████████████████░░░
E           2 warm     0.00  ░░░░░░░░░░░░░░░░░░░░
E         expected level 0.84, confidence 0.75
The threshold defaults to 0.8: holds needs p ≥ 0.8, lacks needs p ≤ 0.2. It must be between 0.5
and 1. Set it per call, per test, or for the whole run:
assert jev.holds(reply, "offers a refund", threshold=0.9)


@pytest.mark.jev(threshold=0.9, model="jev-1.13")
def test_strict(jev): ...
# pytest.ini (or [tool.pytest.ini_options] in pyproject.toml)
[pytest]
jev_model = jev-1.13
jev_threshold = 0.85jev-latest changes when TypeSafe ships a new version, so pin jev-1.13 when runs must be
reproducible.
| Option | ini | Default | |
|---|---|---|---|
--jev-model |
jev_model |
jev-latest |
Jev model to ask |
--jev-threshold |
jev_threshold |
0.8 |
Claim threshold |
--jev-provider |
jev_provider |
auto |
typesafe, openrouter, or auto (OpenRouter if its key is set) |
--jev-no-cache |
off | Ask again instead of reusing cached answers | |
--jev-require |
jev_require |
off | Fail instead of skip when no key is set |
- Tests that use
jevget thejevmarker automatically.pytest -m "not jev"runs everything else offline. - Without a key,
jevtests are skipped and say why. In CI, pass--jev-require(or setjev_require = true) so a missing secret fails the build instead. - Answers are cached by model, text, context and question. Pass
--jev-no-cacheto ask again.
Requests go through the session-scoped jev_client fixture. Override it in conftest.py with
anything that has the TypeSafe SDK's system_one(state=, questions=, model=) method: a fake for
offline unit tests, or an LLM through
system-one-adapter, as the
benchmark does:
# conftest.py
@pytest.fixture(scope="session")
def jev_client():
return LLMJudge("anthropic/claude-haiku-4.5") # bench/llm_judge.pyJev reads claims literally (Jev 1.13 known limits):
- One condition per claim. Write "apologizes" and "offers a refund" as two claims, not one joined with "and".
- Say exactly what you mean. "Says the duplicate payment was refunded" works better than "handles the refund correctly".
- Keep numbers, counts and dates in code.
assert "5 business days" in replyis exact; Jev is not a calculator. - Name the context. "contradicts
docs" points Jev at the right part of the state.
Each call sends one request to Jev's /v1/systemone endpoint with state = {"text": text, **context}. Every claim becomes a Noul question, Does `text` satisfy: <claim>?, which returns
the probability it is true. choice sends a Choice question and score sends a Score question.
The thresholds and comparisons are ordinary Python in this plugin.
- Jev can be wrong. Treat a threshold as a policy you tune on your own cases, and read the failure report before trusting a pass or fail.
- Jev's probabilities move a little between calls. In five calls while this README was written, "says the duplicate payment was refunded" scored between 0.16 and 0.23 on the same reply. The unsure band between 0.2 and 0.8 absorbs this, and the cache keeps reruns identical.
- Text only: no images or audio.
- The text and context you assert on are sent to TypeSafe or OpenRouter. Keep secrets and personal data out of test fixtures.
- Not affiliated with or endorsed by TypeSafe AI.
Issues and pull requests are welcome, especially claims that Jev gets wrong: open an issue with the text, the claim, the probability you got and the one you expected. Ideas being considered for the next versions:
- pass-rate assertions over many sampled replies, for nondeterministic apps
- combined usage summaries with pytest-xdist
- a Vercel AI Gateway provider
uv sync
uv run pytest          # offline: a fake Jev answers every question
uv run ruff check .MIT