
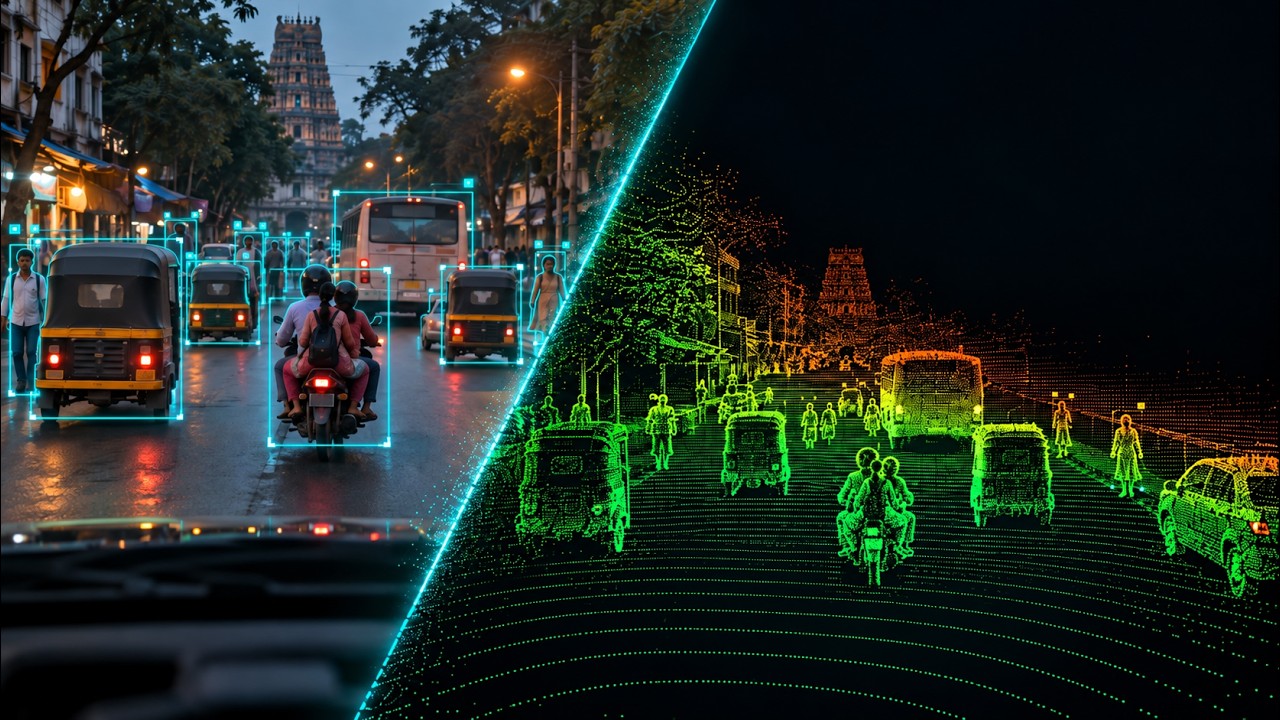
A data engine for autonomous driving, built for Indian roads.
LabeloxAV takes raw fleet footage, machine-labels it through a three-path fusion pipeline, routes every label through a confidence gate to human review, mines the rare and risky moments, and retrains its own models in a closed loop. One ontology, 178 governed classes, tuned for what global datasets never saw: autorickshaws, cattle on the carriageway, overloaded two-wheelers, hand carts, potholes.
Watch the tour, twenty minutes
Every page in the product, narrated, recorded live against the running system. Every number spoken in it
is read from the database at record time, including the ones that do not flatter it.

One command on any machine with Docker:
git clone https://github.com/Sherin-SEF-AI/LabeloxAV.git
cd LabeloxAV
./scripts/install.sh
Generates secrets, migrates the schema, seeds the ontology, creates the first admin, and prints the token.
Open http://localhost:3000.
Or install the Debian package from the latest release,
which puts the tree under /opt/labeloxav and gives you a labeloxav command. It needs Docker too;
the product runs as containers either way.
sudo apt install ./labeloxav_0.1.1_all.deb
sudo labeloxav install
labeloxav url
A first install from an empty image cache takes about six and a half minutes and leaves roughly 4.5 GB of images (api 2.7 GB, web 1.05 GB, database 794 MB), measured on a clean Ubuntu 24.04. No GPU is needed to install: that same install ran with no GPU available, and annotation, review, governance, export and search all work without one. The model paths that need CUDA refuse rather than fabricate. GPU, TLS, and backups: docs/DEPLOY.md.
| Path | Role | Model in this build |
|---|---|---|
path_a_detect |
Closed-set detector | yolo11l.pt (target: YOLO26; weights swap by config) |
path_b_openvocab |
Open-vocabulary + segmentation | YOLO-World + sam2_b.pt |
| (optional) | Mask second opinion | sam_b.pt, off by default - see below |
path_c_vlm |
VLM verifier | qwen2.5vl:7b via Ollama |
The filenames say what runs today; the identity strings in stored provenance keep their historical
spellings. Fused proposals are calibrated (isotonic, fit against a judge whose own error is measured and
corrected for), then gated: auto_accept at 0.45 / safety classes at 0.47 on a calibrated scale.
Those thresholds are configured constants, not measured precision floors - a per-class fit replaces
them where one exists, and the gate logs which it used.
Two segmenters, optionally. With seg_verify: true, SAM 1 is re-prompted with the same box and scores
the mask SAM 2 produced; the agreement lands in provenance and the gate sends anything below 0.80 to review
instead of auto-accepting. Measured on this corpus the two agree at a median mask IoU of 0.893, but a fifth
fall below 0.8 and that fifth is concentrated on riders, motorcycles and autorickshaws, where the mask
boundary is genuinely ambiguous. It is a score, not a fusion - combining the masks would produce a third
one that no ground truth here can check. Costs about 195ms per masked object, so it is off by default.
- 578k objects across 377 sessions; 1,577 human-verified (0.27%) - every downstream number inherits that limit.
- Per-class label precision, measured by a calibrated VLM judge on hash-stable random 80-crop samples:
motorcycle0.87,pedestrian0.87,traffic_sign0.84 ...traffic_signal0.05,object_fallback0.00. Full table: reports/class_precision_2026-08-27.json. - The pooled auto-accepted subset judges at 0.93 strict - machine-judged, not yet measured against humans.
- A blind capture-recapture audit is seeded and unscored, so recall numbers are against labels somebody already found, and the coverage datasheet shipped with every export says so.
The corpus lost 137,904 objects on 2026-08-27: a gap-filling pass had interpolated between track endpoints
that were not the same object, and the result judged at 0.209 against 0.603 for real detections. Reverting
it moved 11 of 13 measured classes up, traffic_sign by 0.146. The engineering
log has the detail.
sherin-sef-ai.github.io/LabeloxAV - full docs, an interactive REST reference generated from the running app, and a Python reference for the stable seams.
The full history of what was built, measured, broken, and fixed - including everything that did not work - is the engineering log.
make up            # infrastructure: Postgres, MinIO, Redis, Redpanda, lakeFS
make install       # deps + migrations + ontology seed
make api           # FastAPI backend on :8000
make web           # Next.js frontend on :3000
make test-unit     # fast tier - green on a fresh clone, no GPU/infra needed
Python 3.11, FastAPI + SQLAlchemy async, Postgres 16 + PostGIS + pgvector, Next.js 14. Import contracts
enforced by lint-imports; domain logic lives in swappable packs (packs/av, packs/sec).
Sherin Joseph Roy - building an India-native, self-improving data engine for autonomous driving.
Apache License 2.0. See LICENSE.
Copyright 2026 Sherin Joseph Roy. You may use, modify and redistribute this software, including commercially, under the terms of that licence. The KITTI raw drives referenced in the documentation are not part of this repository and carry their own licence (CC BY-NC-SA 3.0, KIT and Toyota Technological Institute).