Experiments with Reinforcement Learning to play Atari games. See the original Google Deepmind Atari paper.
This repo is a modified fork of Reinforcement Learning repo authored by @BaptisteBell and @bribridu59.
The following list describes the diff between this fork and the original repo
Training:
- Double DQN
- Removed batch normalization
- Modified hyperparameters
Performance:
- PyTorch compilation
- Fused AdamW optimizer
- TF32 precision
- Gradient clipping
Quality of life:
- CSV exports for rewards and losses during each training run
- Commandline args for profiling and rendering
# Training
python pong.py
python pong.py --enable-perf-logs

# Render Demonstration of model gameplay
python pong.py --demo
python pong.py --demo -m ./models/good_model.pthRendering
Green = good_model.pth
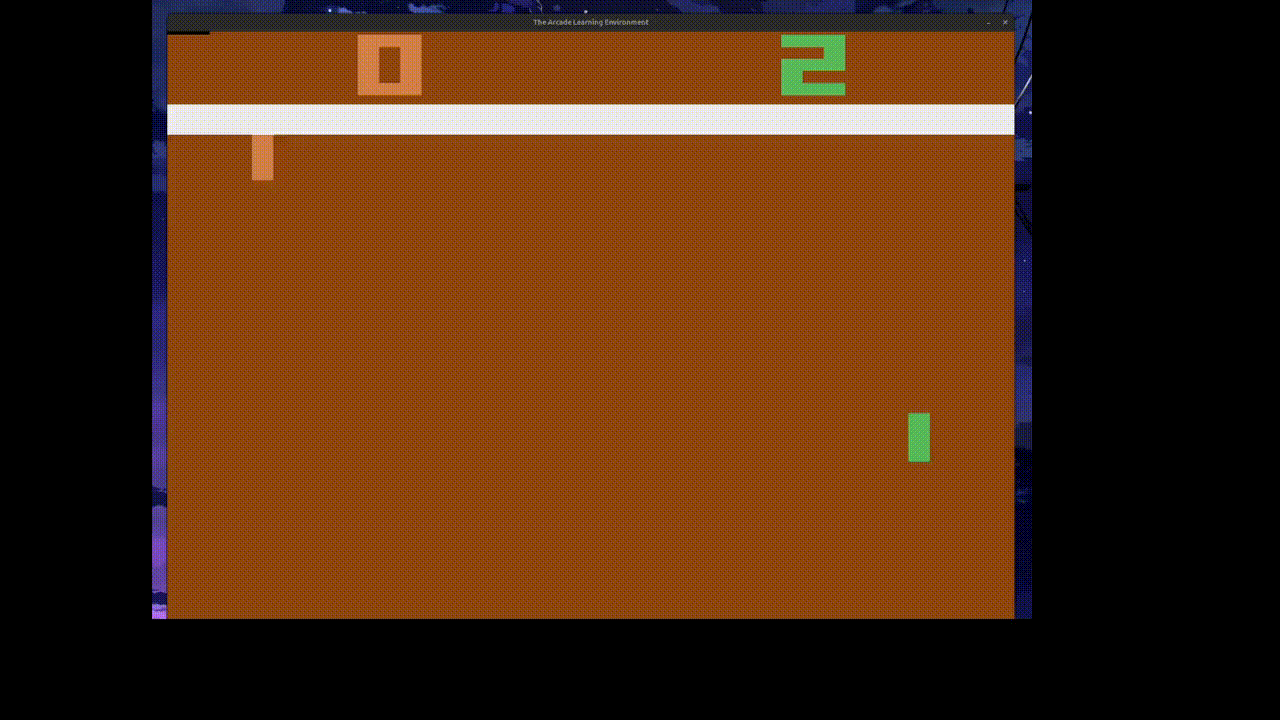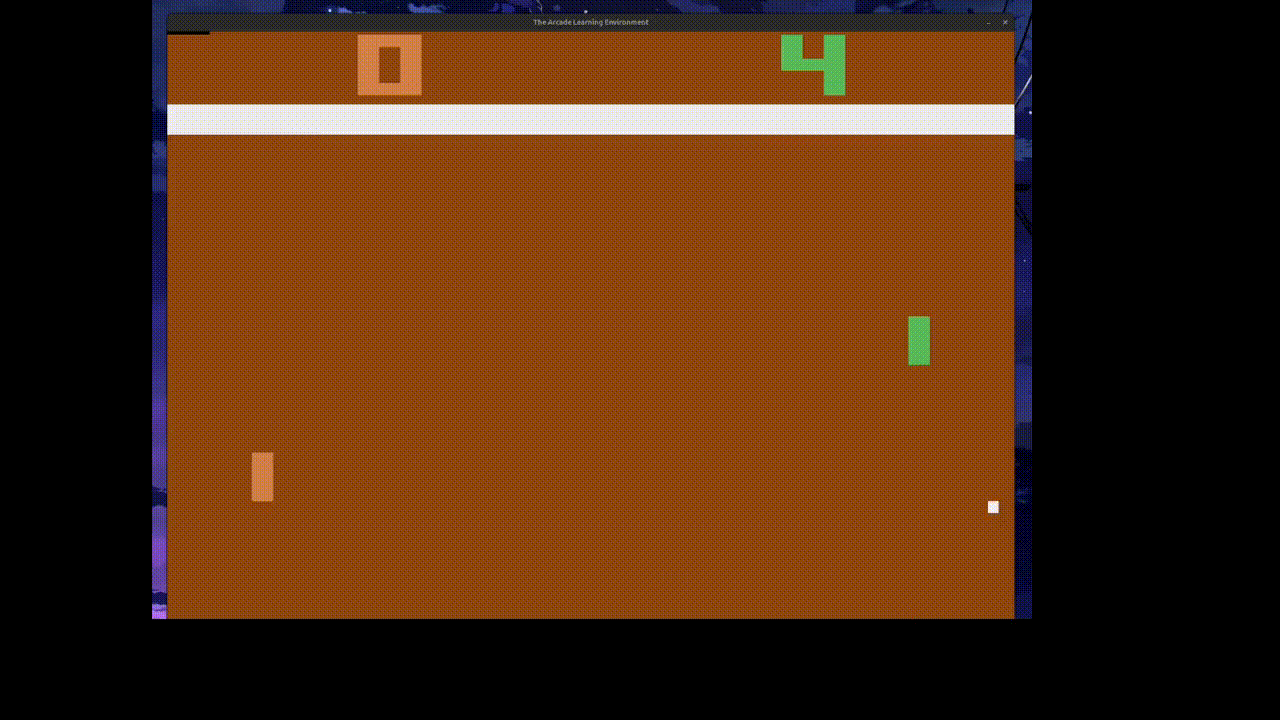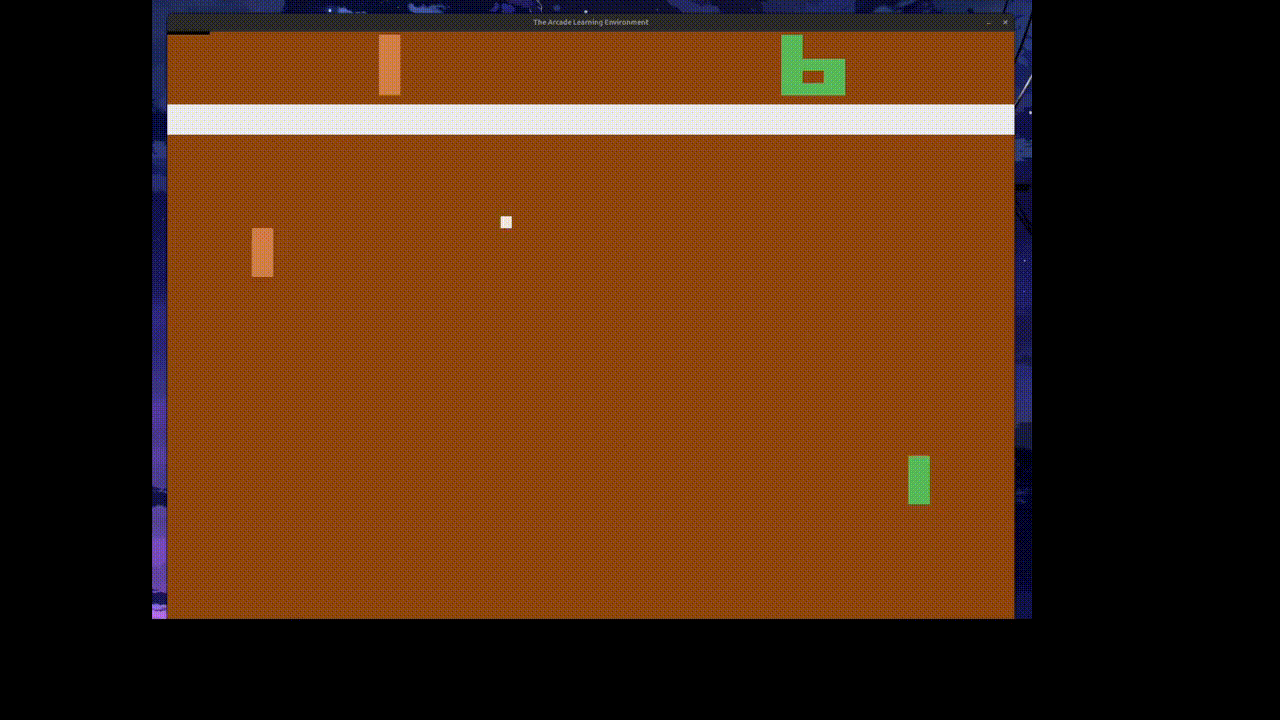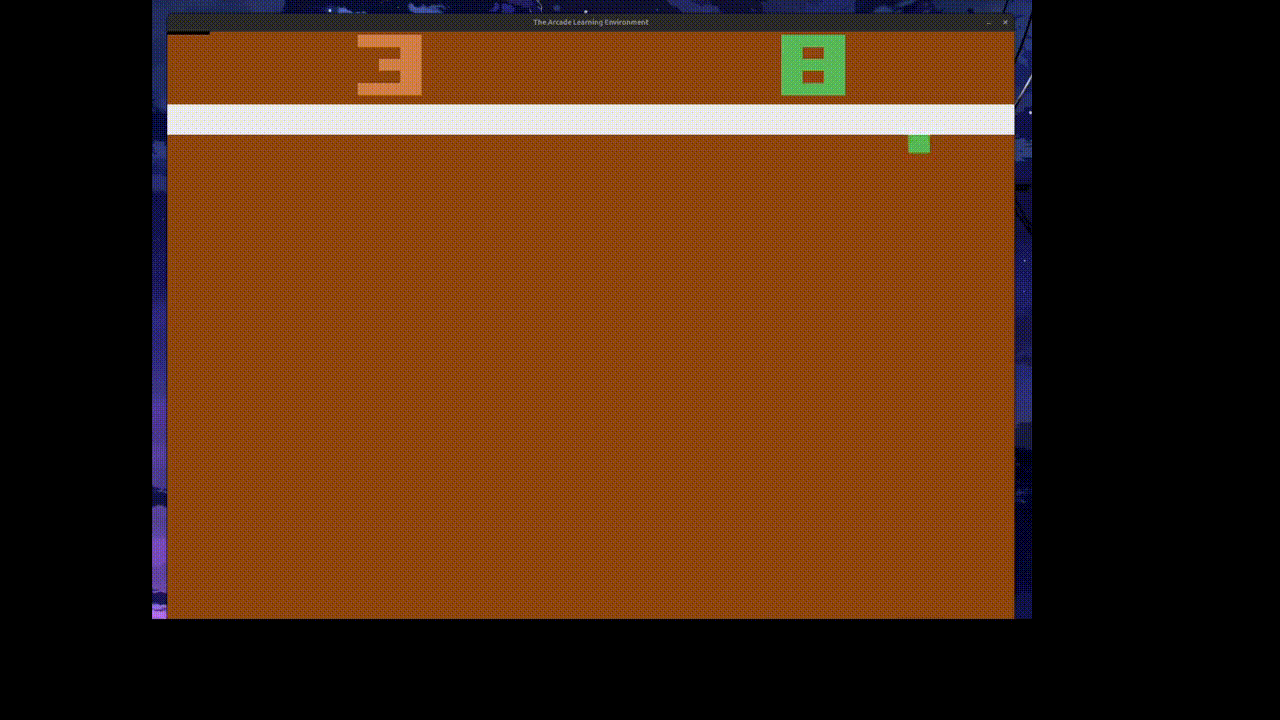
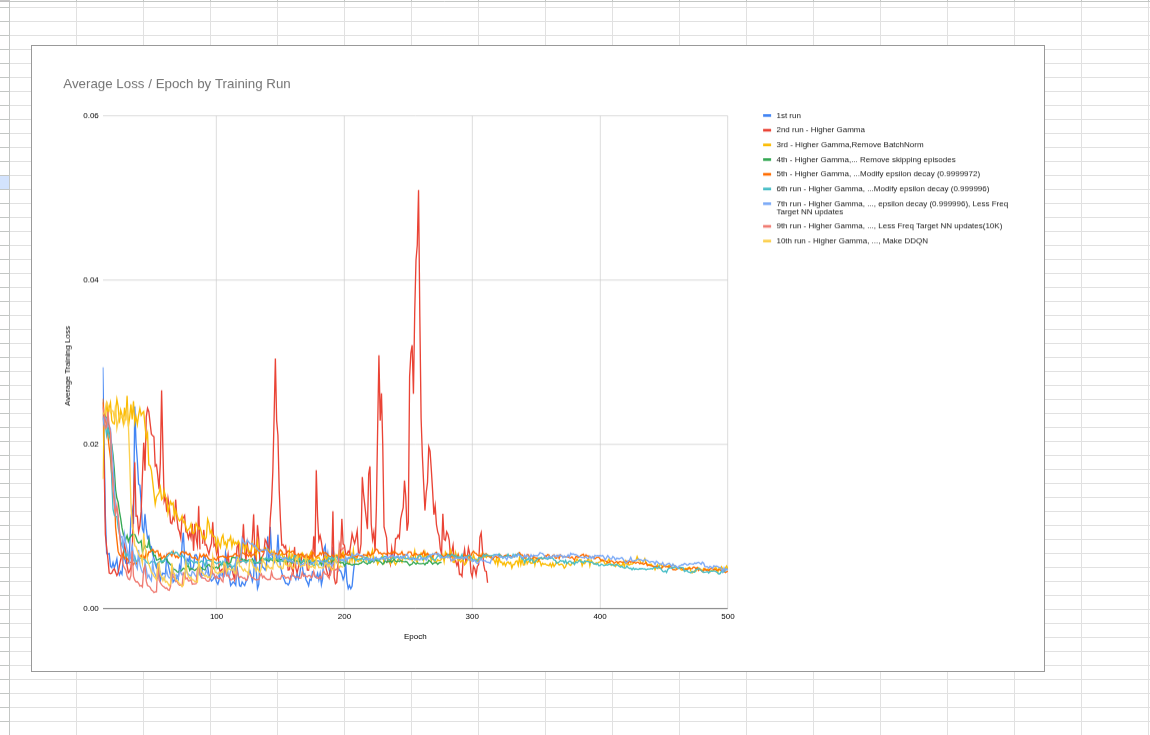
Loss @ 500 episodes (each plot is a unique training run)
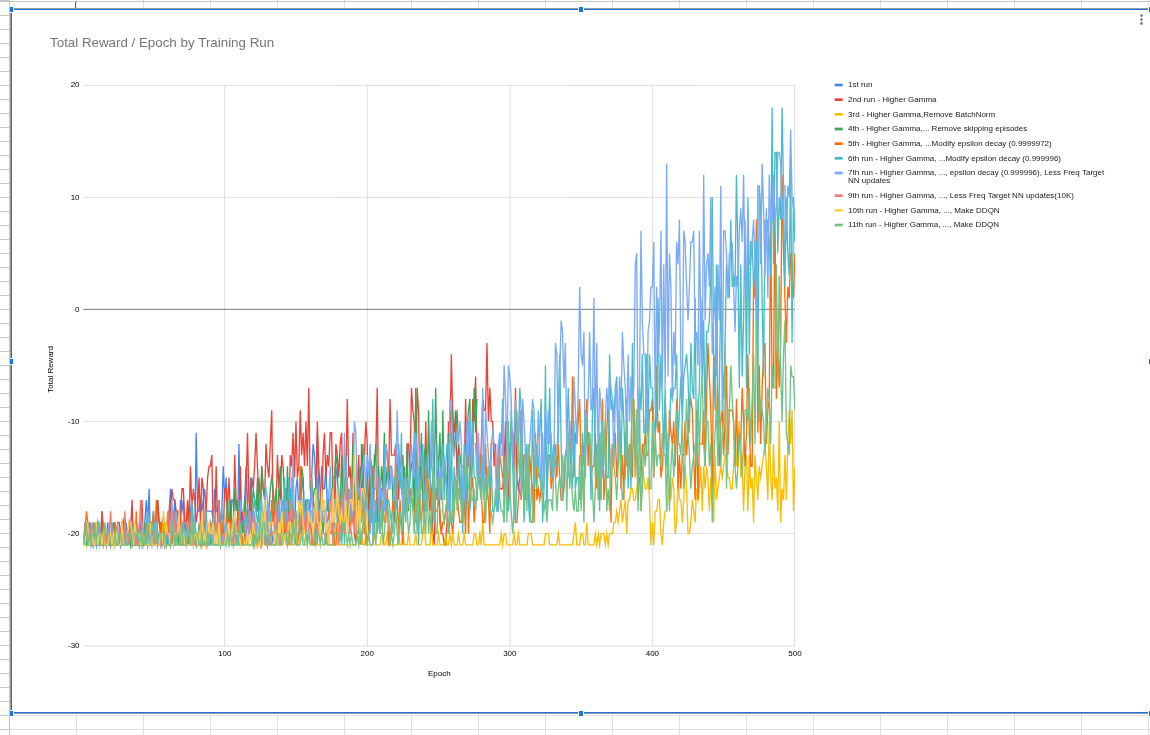
 Reward @ 500 episodes (each plot is a unique training run)