diff --git a/CHANGELOG.md b/CHANGELOG.md
index 6c367b28..0c21fee2 100644
--- a/CHANGELOG.md
+++ b/CHANGELOG.md
@@ -4,6 +4,25 @@ All notable changes to TrialMatchAI are documented here. The format follows
[Keep a Changelog](https://keepachangelog.com/) and the project adheres to
[Semantic Versioning](https://semver.org/).
+## [Unreleased]
+
+### Fixed
+- Eligibility assessment is controlled by `rag.enabled` independently of the CoT
+ prompt setting. Disabling `use_cot_reasoning` now selects direct JSON assessment.
+- Ranked output records assessment controls and availability. Reports explicitly
+ label retrieval-only runs and hide assessments from prior enabled runs.
+- Assessment-control changes invalidate cached matching and per-trial assessment
+ reuse. Legacy matches without mode metadata are recomputed on resume.
+- Shortlist-budget changes invalidate cached assessments. Partial, unavailable,
+ missing, or corrupt assessment outputs remain retryable; fresh attempts isolate
+ their outputs so an early return or failed write cannot revive old verdicts.
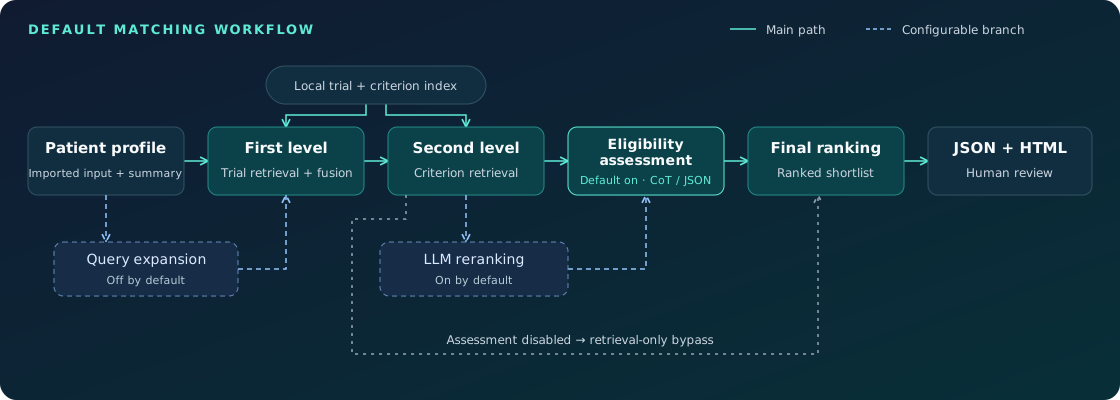
+- The flowchart places eligibility assessment on the default path and labels the
+ explicit retrieval-only bypass. Both SVGs state its default-on behavior.
+
+### Migration
+- Set `rag.enabled: false` to skip assessment. `use_cot_reasoning: false` alone no
+ longer disables it. No new GPU or clinical-accuracy qualification is claimed.
+
## [0.9.0] — 2026-09-12
### Added
diff --git a/README.md b/README.md
index 25425979..b2da9000 100644
--- a/README.md
+++ b/README.md
@@ -15,9 +15,8 @@
TrialMatchAI imports patient information, searches a local clinical-trial index,
-and produces ranked results and portable HTML reports. Optional local models add
-biomedical entity extraction, query expansion, reranking, and criterion-level
-eligibility assessments.
+and produces ranked results and portable HTML reports. Configured local models perform biomedical entity extraction, reranking, and
+criterion-level eligibility assessment. Query expansion can be enabled separately.
**Release status: beta.** The automated release gates exercise the installed CLI
with synthetic data and real CPU search. They do not qualify GPU inference,
@@ -57,7 +56,7 @@ benchmark.
| :--- | :--- | :--- |
| Patient input | Text, FHIR, Phenopacket, and OMOP importers; canonical profiles and summaries | Format coverage is partial; validate mappings against your source data |
| Retrieval | Local LanceDB tables, BM25/vector/hybrid search, multi-channel fusion, structured filters | Retrieval quality depends on corpus, embeddings, filters, and candidate budgets |
-| Model stages | Entity extraction, optional query expansion, LLM reranking, criterion assessments | Requires extra dependencies, model access, and runtime qualification |
+| Model stages | Entity extraction, default-on reranking and eligibility assessment, optional query expansion | Requires extra dependencies, model access, and runtime qualification |
| Review | Ranked JSON, per-trial outputs, individual and multi-patient HTML reports | No hosted clinical workspace, authentication, review queue, or sign-off system |
| Operations | CLI stages, registry updater, checksum tools, synthetic e2e, verified package publishing | Complete cache invalidation, GPU qualification, and application deployment remain open |
| Agent behavior | A fixed sequence of configurable stages, with optional LLM expansion | Bounded retrieval/review agents are planned; autonomous task planning is not implemented |
@@ -68,17 +67,41 @@ across ranking quality, clinical workflow, agents, and delivery.
## How matching works
-
- TrialMatchAI matching flow
- Patient input becomes a canonical profile and summary, then passes through first-level trial retrieval, second-level criterion retrieval, final ranking, and JSON/HTML reports for human review. A local index supports both retrieval stages. Optional query expansion feeds trial retrieval; optional LLM reranking and eligibility assessment feed final ranking.
+
+ TrialMatchAI default matching flow
+ Imported patient profiles pass through first-level trial retrieval, second-level criterion retrieval, eligibility assessment, final ranking, and human review. Eligibility assessment is enabled by default and supports CoT or direct JSON prompts. A local index supports both retrieval stages. Query expansion is off by default; LLM reranking is on by default. Explicitly disabling assessment selects a retrieval-only bypass.
-
- THE MATCHING PIPELINE
- Core path
- Optional model
-
+ DEFAULT MATCHING WORKFLOW
+ Main path
+ Configurable branch
- Patient input Canonical profile
- First level Second level
+ Patient profile First level
+ Second level Eligibility assessment
Final ranking JSON + HTML
- Supported formats Patient summary
- Trial retrieval + fusion Criterion retrieval
+ Imported input + summary Trial retrieval + fusion
+ Criterion retrieval Default on · CoT / JSON
Ranked shortlist Human review
- Local trial + criterion index
+ Local trial + criterion index
-
-
-
+
-
- Query expansion
- LLM reranking
- Eligibility assessment
- CoT / RAG stage
+ Query expansion LLM reranking
+ Off by default
+ On by default
+ Assessment disabled → retrieval-only bypass
diff --git a/docs/assets/readme-overview.svg b/docs/assets/readme-overview.svg
index ce6abbce..1b5e1767 100644
--- a/docs/assets/readme-overview.svg
+++ b/docs/assets/readme-overview.svg
@@ -1,6 +1,6 @@
TrialMatchAI
- Patient profiles flow through trial retrieval and criterion review into ranked reports. A configurable CLI with local search and optional model stages.
+ Patient profiles flow through trial retrieval and criterion review into ranked reports. A configurable CLI with local search and configurable model stages.
Text · FHIR · Phenopacket · OMOP Local lexical + vector search
- Optional model assessments JSON + HTML
+ Assessment enabled by default JSON + HTML
Clear filters
+
@@ -306,6 +310,27 @@
{ cls: "bad", glyph: "✕", title: "Ineligible", match: ["Ineligible"] },
{ cls: "neutral", glyph: "—", title: "Not assessed", match: ["Not assessed"] },
];
+function assessmentLabel(p) {
+ const run = p.run || {};
+ if (run.assessment_status === "no_candidates") return "No candidate trials";
+ if (run.mode === "retrieval_only") return "Retrieval-only";
+ return run.assessment_status === "partial" ? "Eligibility assessment · incomplete" : "Eligibility assessment";
+}
+function renderAssessmentMode() {
+ const run = CUR.run || {};
+ let detail = "Model assessments are available. Review their evidence and criterion coverage.";
+ if (run.assessment_status === "no_candidates") detail = "No candidates were available for eligibility assessment.";
+ else if (run.mode === "retrieval_only") {
+ detail = run.assessment_status === "disabled"
+ ? "Eligibility assessment was disabled. Scores reflect retrieval relevance only."
+ : "No usable eligibility assessment is available. These results are a retrieval shortlist.";
+ } else if (run.assessment_status === "partial") {
+ detail = "Some candidate assessments are missing or unusable. Unassessed trials have no eligibility verdict.";
+ }
+ const node = document.getElementById("assessment-mode");
+ node.textContent = "";
+ node.append(el("strong", { text: assessmentLabel(CUR) }), el("span", { text: detail }));
+}
function overviewRow(p) {
const pt = p.patient || {}, trials = p.trials || [];
const info = el("div", { class: "pinfo" });
@@ -314,6 +339,7 @@
if (pt.age != null) bits.push("Age " + pt.age);
if (pt.sex) bits.push(pt.sex);
bits.push(trials.length + (trials.length === 1 ? " trial" : " trials"));
+ bits.push(assessmentLabel(p));
info.append(el("div", { class: "pmeta", text: bits.join(" · ") }));
const tally = el("div", { class: "tally" });
for (const tier of TALLY) {
@@ -488,6 +514,7 @@
const ta = document.getElementById("toggle-all");
ta.setAttribute("aria-pressed", "false"); ta.textContent = "Expand all";
renderPatientCard();
+ renderAssessmentMode();
fillSelect("f-status", (p.trials || []).map(t => (t.meta || {}).overall_status), "All statuses");
fillSelect("f-phase", (p.trials || []).map(t => (t.meta || {}).phase), "All phases");
fillVerdict();
diff --git a/src/trialmatchai/main.py b/src/trialmatchai/main.py
index fd01075a..3f529a41 100644
--- a/src/trialmatchai/main.py
+++ b/src/trialmatchai/main.py
@@ -2,6 +2,8 @@
from contextlib import nullcontext
from pathlib import Path
+from shutil import copyfile
+from tempfile import TemporaryDirectory
from typing import TYPE_CHECKING, Any, Dict, List, Mapping, Optional, Tuple
from trialmatchai.config.config_loader import load_config
@@ -27,13 +29,19 @@
from trialmatchai.interop.models import PatientProfile
from trialmatchai.utils.file_utils import (
create_directory,
- is_valid_json_file,
read_json_file,
read_text_file,
write_json_file,
write_text_file,
)
from trialmatchai.schemas.phenopacket import Keywords
+from trialmatchai.matching.assessment import (
+ assessment_enabled as _rag_enabled,
+ assessment_run_info,
+ has_assessment_output,
+ match_is_complete,
+ reusable_assessment_ids,
+)
from trialmatchai.utils.logging_config import reset_request_id, set_request_id, setup_logging
from trialmatchai.utils.timing import log_timing
@@ -367,17 +375,20 @@ def run_rag_processing(
top_trials_file: str,
patient_info: Dict,
config: Dict,
-):
+) -> List[Dict]:
top_trials = read_text_file(top_trials_file)
if not top_trials:
logger.error("No top trials available for RAG processing.")
- return
+ return []
top_trials = top_trials[: config["rag"].get("max_trials_rag", 20)]
- patient_narrative = patient_info.get("patient_narrative", [])
+ patient_narrative = [
+ str(line).strip() for line in (patient_info.get("patient_narrative") or [])
+ if str(line).strip()
+ ]
if not patient_narrative:
logger.error("No patient narrative available for RAG processing.")
- return
+ return []
rag_cfg = config.get("rag", {})
rag_backend = str(rag_cfg.get("backend", "vllm"))
@@ -391,7 +402,7 @@ def run_rag_processing(
model_path=config["model"]["base_model"],
device=str(config.get("global", {}).get("device", "cpu")),
batch_size=rag_cfg.get("batch_size", 1),
- use_cot=config.get("use_cot_reasoning", False),
+ use_cot=config.get("use_cot_reasoning", True),
max_new_tokens=vllm_cfg.get("max_new_tokens", 256),
temperature=vllm_cfg.get("temperature", 0.0),
top_p=vllm_cfg.get("top_p", 1.0),
@@ -430,14 +441,39 @@ def run_rag_processing(
else:
raise ValueError(f"Unsupported rag.backend: {rag_backend}")
- rag_processor.process_trials(
- nct_ids=top_trials,
- json_folder=_criteria_source_folders(config),
- output_folder=output_folder,
- patient_narrative=patient_narrative,
- )
+ output_path = Path(output_folder)
+ reusable = reusable_assessment_ids(output_path / "ranked_trials.json", config)
+ # A fresh attempt cannot see prior outputs unless the saved run explicitly
+ # associates them with the same controls. Failed/aborted writes cannot revive
+ # an old verdict, including when a backend logs a save error and continues.
+ with TemporaryDirectory(prefix=".assessment-", dir=output_folder) as staging:
+ stage_path = Path(staging)
+ for trial_id in reusable.intersection(top_trials):
+ for suffix in (".txt", ".json"):
+ source = output_path / f"{trial_id}{suffix}"
+ if source.is_file():
+ copyfile(source, stage_path / source.name)
+ rag_processor.process_trials(
+ nct_ids=top_trials,
+ json_folder=_criteria_source_folders(config),
+ output_folder=staging,
+ patient_narrative=patient_narrative,
+ )
+ trial_data = load_trial_data(staging, allowed_ids=set(top_trials))
+ for trial in trial_data:
+ trial_id = trial["TrialID"]
+ if trial_id in reusable:
+ continue
+ text_path = stage_path / f"{trial_id}.txt"
+ if not text_path.exists():
+ # A replacement JSON without text must not inherit old reasoning.
+ text_path.write_text("", encoding="utf-8")
+ text_path.replace(output_path / text_path.name)
+ json_path = stage_path / f"{trial_id}.json"
+ json_path.replace(output_path / json_path.name)
write_json_file({"status": "done"}, f"{output_folder}/rag_output.json")
logger.info("RAG-based trial matching complete.")
+ return trial_data
def _rag_final_ranking(
@@ -452,13 +488,13 @@ def _rag_final_ranking(
retrievable shortlist isn't silently discarded as an empty ranked_trials.json.
"""
ranked_trials = rank_trials(
- trial_data,
+ trial_data if any(has_assessment_output(trial) for trial in trial_data) else [],
first_level_scores=first_level_scores,
second_level_scores=second_level_scores,
)
if not ranked_trials and semi_final_trials:
logger.warning(
- "RAG produced no per-trial outputs; ranking by retrieval scores."
+ "No usable eligibility assessment outputs; ranking by retrieval scores."
)
ranked_trials = [
{"TrialID": trial_id, "Score": score}
@@ -588,8 +624,8 @@ def main_pipeline(
output_folder = Path(paths["output_dir"]) / patient_id
if resume:
ranked_path = output_folder / "ranked_trials.json"
- # Parseable (not just non-empty): a truncated marker re-runs, an empty-but-valid result counts as done.
- if is_valid_json_file(str(ranked_path)):
+ # Resume only current assessment controls; legacy or changed modes re-run.
+ if match_is_complete(ranked_path, config):
logger.info("Resume: skipping already-matched patient %s", patient_id)
skipped_patients += 1
continue
@@ -646,10 +682,11 @@ def main_pipeline(
patient_context,
)
+ trial_data = []
if _rag_enabled(config):
with log_timing(logger, "RAG processing"):
with _inference_context(torch):
- run_rag_processing(
+ trial_data = run_rag_processing(
str(output_folder),
top_trials_path,
patient_info,
@@ -659,28 +696,27 @@ def main_pipeline(
with log_timing(logger, "Final ranking"):
# Scope to this run's shortlist so stale per-trial files aren't ranked.
shortlist_ids = {trial_id for trial_id, _ in semi_final_trials}
- trial_data = load_trial_data(
- str(output_folder), allowed_ids=shortlist_ids
- )
+ trial_data = [trial for trial in trial_data if trial["TrialID"] in shortlist_ids]
ranked_trials = _rag_final_ranking(
trial_data,
semi_final_trials,
first_level_scores=first_level_scores,
second_level_scores=second_level_scores,
)
- save_ranked_trials(
- ranked_trials, str(output_folder / "ranked_trials.json")
- )
else:
logger.info("RAG processing disabled; ranking by retrieval scores.")
- save_ranked_trials(
- [
- {"TrialID": trial_id, "Score": score}
- for trial_id, score in semi_final_trials
- ],
- str(output_folder / "ranked_trials.json"),
- )
-
+ ranked_trials = [
+ {"TrialID": trial_id, "Score": score}
+ for trial_id, score in semi_final_trials
+ ]
+
+ run_info = assessment_run_info(config, trial_data, {tid for tid, _ in semi_final_trials})
+ save_ranked_trials(ranked_trials, str(output_folder / "ranked_trials.json"), run_info=run_info)
+ if run_info["mode"] == "retrieval_only":
+ logger.info("Result mode: retrieval-only; no eligibility assessment is available (%s).",
+ run_info["assessment_status"])
+ else:
+ logger.info("Result mode: eligibility assessment (%s).", run_info["assessment_status"])
_maybe_write_report(output_folder, config)
logger.info("Pipeline completed for patient %s", patient_id)
completed_patients += 1
@@ -781,12 +817,6 @@ def _reranker_backend(config: Dict) -> str:
return str(config.get("LLM_reranker", {}).get("backend", "vllm"))
-def _rag_enabled(config: Dict) -> bool:
- if not bool(config.get("use_cot_reasoning", True)):
- return False
- return bool(config.get("rag", {}).get("enabled", True))
-
-
def _inference_context(torch_module):
if torch_module is None:
return nullcontext()
diff --git a/src/trialmatchai/matching/assessment.py b/src/trialmatchai/matching/assessment.py
new file mode 100644
index 00000000..3b08cca2
--- /dev/null
+++ b/src/trialmatchai/matching/assessment.py
@@ -0,0 +1,122 @@
+"""Shared assessment controls and result provenance for matching and reporting."""
+
+from __future__ import annotations
+
+import json
+from collections.abc import Mapping
+from pathlib import Path
+
+
+def assessment_enabled(config: Mapping) -> bool:
+ """Eligibility assessment is default-on, independently of its prompt style."""
+ return bool(config.get("rag", {}).get("enabled", True))
+
+
+def assessment_settings(config: Mapping) -> dict:
+ return {
+ "enabled": assessment_enabled(config),
+ "use_cot_reasoning": bool(config.get("use_cot_reasoning", True)),
+ "backend": config.get("rag", {}).get("backend", "vllm"),
+ "no_think": bool(config.get("rag", {}).get("no_think", False)),
+ "max_trials_rag": config.get("rag", {}).get("max_trials_rag", 20),
+ }
+
+
+def has_assessment_output(value: object) -> bool:
+ """Recognize an assessment payload, without claiming clinical completeness."""
+ if not isinstance(value, Mapping) or "error" in value:
+ return False
+ decision = value.get("Final Decision")
+ if isinstance(decision, str) and decision.strip():
+ return True
+ return any(
+ isinstance(items := value.get(key), list)
+ and any(isinstance(item, Mapping) and item.get("Classification") for item in items)
+ for key in ("Inclusion_Criteria_Evaluation", "Exclusion_Criteria_Evaluation")
+ )
+
+
+def _matching_run(path: str | Path, config: Mapping) -> dict:
+ try:
+ result = json.loads(Path(path).read_text(encoding="utf-8"))
+ run = result.get("Run", {})
+ if (
+ isinstance(result.get("RankedTrials"), list)
+ and isinstance(run, dict)
+ and run.get("schema_version") == 1
+ and run.get("assessment") == assessment_settings(config)
+ ):
+ return run
+ except (OSError, ValueError, AttributeError):
+ pass
+ return {}
+
+
+def match_controls_current(path: str | Path, config: Mapping) -> bool:
+ """Compare assessment controls, independently of completion or retryability.
+
+ This binds only assessment controls, not all patient/corpus/model inputs.
+ """
+ return bool(_matching_run(path, config))
+
+
+def reusable_assessment_ids(path: str | Path, config: Mapping) -> set[str]:
+ """Only outputs explicitly associated with a compatible run may be reused."""
+ run = _matching_run(path, config)
+ ids = run.get("assessed_trial_ids")
+ if run.get("mode") != "eligibility_assessment" or not isinstance(ids, list):
+ return set()
+ available = set()
+ for trial_id in ids:
+ # Per-trial outputs are NCT files, never paths supplied by result metadata.
+ if not isinstance(trial_id, str) or not trial_id.isalnum() or not trial_id.upper().startswith("NCT"):
+ continue
+ try:
+ data = json.loads((Path(path).parent / f"{trial_id}.json").read_text(encoding="utf-8"))
+ except (OSError, ValueError):
+ continue
+ if has_assessment_output(data):
+ available.add(trial_id)
+ return available
+
+
+def match_is_complete(path: str | Path, config: Mapping) -> bool:
+ """Incomplete/failed assessments stay pending; intentional bypasses are final."""
+ run = _matching_run(path, config)
+ if not run:
+ return False
+ status = run.get("assessment_status")
+ if not assessment_enabled(config):
+ return status == "disabled"
+ if status == "no_candidates":
+ return run.get("candidate_count") == 0 and run.get("assessed_trial_ids") == []
+ if status != "outputs_available":
+ return False
+ available = reusable_assessment_ids(path, config)
+ return bool(available) and len(available) == run.get("candidate_count")
+
+
+def assessment_run_info(config: Mapping, trial_data: list[dict], candidate_ids: set[str]) -> dict:
+ settings = assessment_settings(config)
+ assessed_ids = sorted({
+ trial["TrialID"] for trial in trial_data
+ if settings["enabled"] and trial.get("TrialID") in candidate_ids and has_assessment_output(trial)
+ })
+ if not settings["enabled"]:
+ status = "disabled"
+ elif not candidate_ids:
+ status = "no_candidates"
+ elif not assessed_ids:
+ status = "unavailable"
+ elif len(assessed_ids) < len(candidate_ids):
+ status = "partial"
+ else:
+ status = "outputs_available"
+ return {
+ "schema_version": 1,
+ "assessment": settings,
+ "mode": "eligibility_assessment" if assessed_ids else "retrieval_only",
+ "assessment_status": status,
+ "assessed_trial_ids": assessed_ids,
+ "candidate_count": len(candidate_ids),
+ }
diff --git a/src/trialmatchai/matching/trial_ranker.py b/src/trialmatchai/matching/trial_ranker.py
index 61eb060a..78b07add 100644
--- a/src/trialmatchai/matching/trial_ranker.py
+++ b/src/trialmatchai/matching/trial_ranker.py
@@ -159,10 +159,13 @@ def rank_trials(
return ranked_trials
-def save_ranked_trials(ranked_trials: List[Dict], output_file: str):
+def save_ranked_trials(ranked_trials: List[Dict], output_file: str, *, run_info: Dict | None = None):
# Do NOT swallow write failures: the caller treats a clean return as a completed
# patient, so a failed final write must surface to retry it (not mark it done).
- write_json_file({"RankedTrials": ranked_trials}, output_file)
+ payload = {"RankedTrials": ranked_trials}
+ if run_info is not None:
+ payload["Run"] = run_info
+ write_json_file(payload, output_file)
logger.info(f"Ranked trials saved to {output_file}")
@@ -176,7 +179,11 @@ def rerank_patient_dir(patient_dir: str) -> int:
ranked_path = os.path.join(patient_dir, "ranked_trials.json")
if not os.path.exists(ranked_path):
return 0
- existing = (read_json_file(ranked_path) or {}).get("RankedTrials", [])
+ payload = read_json_file(ranked_path) or {}
+ run_info = payload.get("Run")
+ if isinstance(run_info, dict) and run_info.get("mode") == "retrieval_only":
+ return 0 # Old assessment files do not belong to this retrieval-only result.
+ existing = payload.get("RankedTrials", [])
shortlist_ids = {r["TrialID"] for r in existing if isinstance(r, dict) and r.get("TrialID")}
if not shortlist_ids:
return 0
@@ -197,5 +204,5 @@ def rerank_patient_dir(patient_dir: str) -> int:
ranked = rank_trials(
trial_data, first_level_scores=first_level, second_level_scores=second_level
)
- save_ranked_trials(ranked, ranked_path)
+ save_ranked_trials(ranked, ranked_path, run_info=run_info)
return len(ranked)
diff --git a/src/trialmatchai/orchestration.py b/src/trialmatchai/orchestration.py
index 57fcddd9..a7c61fd0 100644
--- a/src/trialmatchai/orchestration.py
+++ b/src/trialmatchai/orchestration.py
@@ -366,24 +366,28 @@ def build_index(
# --------------------------------------------------------------------------- #
def count_pending(config: Dict[str, Any]) -> tuple[int, int]:
"""Return (pending, done) patient counts for the configured dirs."""
+ from trialmatchai.matching.assessment import match_is_complete
+
patient_cfg = config.get("patient_inputs", {})
profile_dir = Path(patient_cfg.get("profile_dir", "data/patients/profiles"))
output_dir = Path(config["paths"]["output_dir"])
pending = done = 0
for profile_path in sorted(profile_dir.glob("*.json")):
ranked = output_dir / profile_path.stem / "ranked_trials.json"
- if is_valid_json_file(str(ranked)):
+ if match_is_complete(ranked, config):
done += 1
else:
pending += 1
return pending, done
-_MATCH_STATE_VERSION = "1"
+_MATCH_STATE_VERSION = "2"
def _match_signature(config: Dict[str, Any]) -> dict:
"""Match-relevant config whose change should invalidate cached patient matches."""
+ from trialmatchai.matching.assessment import assessment_settings
+
reranker = config.get("LLM_reranker", {})
model = config.get("model", {})
return {
@@ -394,7 +398,7 @@ def _match_signature(config: Dict[str, Any]) -> dict:
"reranker_adapter": model.get("reranker_adapter_path"),
"reranker_revision": model.get("reranker_model_revision"),
"cot_model": model.get("base_model"),
- "use_cot": config.get("use_cot_reasoning"),
+ "assessment": assessment_settings(config),
"query_expansion": (config.get("query_expansion") or {}).get("enabled"),
"candidate_limit": (config.get("search_backend") or {}).get("candidate_limit"),
"search_mode": (config.get("search") or {}).get("mode"),
diff --git a/src/trialmatchai/services/preflight.py b/src/trialmatchai/services/preflight.py
index 025a0fc8..5af96db4 100644
--- a/src/trialmatchai/services/preflight.py
+++ b/src/trialmatchai/services/preflight.py
@@ -4,6 +4,7 @@
from pathlib import Path
from typing import Any, Dict, List
+from trialmatchai.matching.assessment import assessment_enabled as _rag_enabled
from trialmatchai.utils.logging_config import setup_logging
logger = setup_logging(__name__)
@@ -293,12 +294,6 @@ def _reranker_enabled(config: Dict[str, Any]) -> bool:
return bool(config.get("LLM_reranker", {}).get("enabled", True))
-def _rag_enabled(config: Dict[str, Any]) -> bool:
- if not bool(config.get("use_cot_reasoning", True)):
- return False
- return bool(config.get("rag", {}).get("enabled", True))
-
-
def _reranker_backend(config: Dict[str, Any]) -> str:
return str(config.get("LLM_reranker", {}).get("backend", "vllm"))
diff --git a/tests/test_assessment_modes.py b/tests/test_assessment_modes.py
new file mode 100644
index 00000000..e9afd37b
--- /dev/null
+++ b/tests/test_assessment_modes.py
@@ -0,0 +1,342 @@
+from __future__ import annotations
+
+import json
+from pathlib import Path
+
+import pytest
+
+from trialmatchai.matching.assessment import assessment_run_info, assessment_settings, match_controls_current, match_is_complete
+from trialmatchai.matching.eligibility_base import BaseTrialProcessor
+from trialmatchai.utils.file_utils import write_json_file, write_text_file
+
+
+@pytest.mark.parametrize("enabled", [True, False])
+@pytest.mark.parametrize("cot", [True, False])
+def test_preflight_checks_assessment_even_without_cot(tmp_path, monkeypatch, enabled, cot):
+ from trialmatchai.services import preflight
+
+ checked = []
+ monkeypatch.setattr(preflight, "check_hf_access", lambda models: checked.extend(models) or [])
+ monkeypatch.setattr(preflight.importlib.util, "find_spec", lambda name: object())
+ config = {
+ "paths": {"output_dir": str(tmp_path)}, "LLM_reranker": {"enabled": False},
+ "rag": {"enabled": enabled, "backend": "transformers"}, "use_cot_reasoning": cot,
+ "model": {"base_model": "test/assessment"},
+ }
+ assert preflight.run_preflight_checks(config, require_models=True) == []
+ assert checked == (["test/assessment"] if enabled else [])
+
+
+def test_default_assessment_remains_enabled_with_direct_json_prompt():
+ from trialmatchai.main import _rag_enabled
+
+ assert _rag_enabled({"use_cot_reasoning": False})
+ proc = BaseTrialProcessor()
+ proc.use_cot = False
+ prompt = proc._format_prompt("Adults with lung cancer", "Adult with lung cancer")
+ assert "Inclusion_Criteria_Evaluation" in prompt and "Exclusion_Criteria_Evaluation" in prompt
+ assert "Final Decision" in prompt
+ assert "chain of thoughts" not in prompt
+
+
+@pytest.fixture
+def pipeline(tmp_path, monkeypatch):
+ import trialmatchai.main as main
+ import trialmatchai.models.embedding as embedding
+ from trialmatchai.interop.models import PatientProfile
+ from trialmatchai.matching import eligibility_reasoning_transformers as backend
+ from trialmatchai.matching import eligibility_reasoning_vllm as vllm_backend
+ from trialmatchai.models.llm import vllm_loader
+
+ config = {
+ "paths": {"output_dir": str(tmp_path / "results"), "trials_json_folder": str(tmp_path / "trials")},
+ "patient_inputs": {"profile_dir": str(tmp_path / "profiles")},
+ "search": {"mode": "bm25"}, "LLM_reranker": {"enabled": False},
+ "rag": {"enabled": True, "backend": "transformers"}, "use_cot_reasoning": False,
+ "model": {"base_model": "test-model"}, "reporting": {"emit_html": True},
+ }
+ profile = PatientProfile.model_validate({"patient_id": "P1", "demographics": {}})
+ summary = {"patient_id": "P1", "main_conditions": ["lung cancer"], "other_conditions": [],
+ "patient_narrative": ["Adult with lung cancer"], "age": "all", "gender": "all"}
+ write_json_file(profile.model_dump(mode="json"), str(tmp_path / "profiles/P1.json"))
+ write_json_file({"eligibility_criteria": "Inclusion: Adults with lung cancer"}, str(tmp_path / "trials/NCT1.json"))
+ monkeypatch.setattr(main, "build_search_backend", lambda cfg: object())
+ monkeypatch.setattr(main, "run_preflight_checks", lambda *a, **kw: [])
+ monkeypatch.setattr(main, "_load_patient_inputs", lambda cfg: [(profile, summary)])
+ monkeypatch.setattr(embedding, "build_embedder", lambda cfg: object())
+ monkeypatch.setattr(main, "build_entity_annotator", lambda *a, **kw: None)
+ monkeypatch.setattr(main, "SecondStageRetriever", lambda **kw: object())
+ monkeypatch.setattr(main, "run_first_level_search", lambda *a, **kw: (["NCT1"], ["lung cancer"], [], summary["patient_narrative"], {"NCT1": 0.7}))
+
+ def second(*args):
+ path = str(Path(args[0]) / "top_trials.txt")
+ write_text_file(["NCT1"], path)
+ return [("NCT1", 0.7)], path, {"NCT1": 0.7}
+
+ monkeypatch.setattr(main, "run_second_level_search", second)
+ calls = []
+
+ class FakeProcessor(BaseTrialProcessor):
+ def __init__(self, **kwargs):
+ self.use_cot = kwargs["use_cot"]
+
+ def _process_batch(self, items, output_folder):
+ calls.append(self.use_cot)
+ for item in items:
+ self._save_outputs(item["nct_id"], json.dumps({
+ "Final Decision": "Eligible",
+ "Inclusion_Criteria_Evaluation": [{"Criterion": "Lung cancer", "Classification": "Met", "Justification": "Recorded."}],
+ "Exclusion_Criteria_Evaluation": [],
+ }), output_folder)
+
+ monkeypatch.setattr(backend, "BatchTrialProcessorTransformers", FakeProcessor)
+ monkeypatch.setattr(vllm_backend, "BatchTrialProcessorVLLM", FakeProcessor)
+ monkeypatch.setattr(vllm_loader, "load_vllm_engine", lambda **kw: (None, None, None))
+ return main, config, calls, tmp_path / "results/P1"
+
+
+@pytest.mark.parametrize("backend_name", ["transformers", "vllm"])
+def test_full_pipeline_assesses_when_cot_is_off(pipeline, backend_name):
+ main, config, calls, output = pipeline
+ config["rag"]["backend"] = backend_name
+ assert main.main_pipeline(config=config) == 0
+ assert calls == [False]
+ ranked = json.loads((output / "ranked_trials.json").read_text())
+ assert ranked["Run"]["mode"] == "eligibility_assessment"
+ assert ranked["Run"]["assessment_status"] == "outputs_available"
+ assert ranked["Run"]["assessed_trial_ids"] == ["NCT1"]
+ assert '"final_decision": "Eligible"' in (output / "report.html").read_text()
+
+
+def test_mode_changes_invalidate_resume_and_hide_old_assessments(pipeline):
+ from trialmatchai.interop.exporters.html_report import profile_to_model
+ from trialmatchai.matching.trial_ranker import rerank_patient_dir
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ assert main.main_pipeline(config=config) == 0
+ assert count_pending(config) == (0, 1)
+ (output / "NCT1.txt").write_text("old reasoning ")
+ config["rag"]["enabled"] = False
+ assert count_pending(config) == (1, 0)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False] # Assessment was not invoked again.
+ assert (output / "NCT1.json").exists() # Old output remains but cannot leak into this run.
+ payload = json.loads((output / "ranked_trials.json").read_text())
+ assert payload["Run"]["mode"] == "retrieval_only"
+ assert payload["Run"]["assessment_status"] == "disabled"
+ report = profile_to_model(output)
+ trial = report["trials"][0]
+ assert trial["final_decision"] is None and trial["inclusion"] == [] and trial["cot"] is None
+ assert not trial["reasoning_available"]
+ assert rerank_patient_dir(str(output)) == 0
+ assert json.loads((output / "ranked_trials.json").read_text()) == payload
+ config["rag"]["enabled"] = True
+ assert count_pending(config) == (1, 0)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, False] # Re-enabling recomputes, including per-trial outputs.
+
+
+def test_cot_style_change_recomputes_per_trial_outputs(pipeline):
+ main, config, calls, output = pipeline
+ assert main.main_pipeline(config=config) == 0
+ config["use_cot_reasoning"] = True
+ assert not match_controls_current(output / "ranked_trials.json", config)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, True]
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, True] # Unchanged settings preserve resume.
+
+
+def test_missing_or_error_assessments_produce_retrieval_only_results():
+ from trialmatchai.main import _rag_final_ranking
+
+ data = [{"TrialID": "NCT1", "error": "invalid_json_response"}]
+ assert _rag_final_ranking(data, [("NCT1", 0.7)]) == [{"TrialID": "NCT1", "Score": 0.7}]
+ info = assessment_run_info({}, data, {"NCT1"})
+ assert info["mode"] == "retrieval_only" and info["assessment_status"] == "unavailable"
+ assert info["assessment"]["enabled"] is True
+
+
+def test_legacy_results_require_recomputation_for_new_control_semantics(tmp_path):
+ path = tmp_path / "ranked_trials.json"
+ path.write_text('{"RankedTrials": []}')
+ assert not match_controls_current(path, {})
+ write_json_file({"RankedTrials": [], "Run": assessment_run_info({}, [], set())}, str(path))
+ assert match_controls_current(path, {})
+ assert not match_controls_current(path, {"use_cot_reasoning": False})
+
+
+def test_reranking_assessed_results_preserves_run_metadata(tmp_path):
+ from trialmatchai.matching.trial_ranker import rerank_patient_dir
+
+ data = {"TrialID": "NCT1", "Final Decision": "Eligible", "Inclusion_Criteria_Evaluation": []}
+ run = assessment_run_info({}, [data], {"NCT1"})
+ write_json_file(data, str(tmp_path / "NCT1.json"))
+ write_json_file({"RankedTrials": [{"TrialID": "NCT1", "Score": 1}], "Run": run}, str(tmp_path / "ranked_trials.json"))
+ assert rerank_patient_dir(str(tmp_path)) == 1
+ assert json.loads((tmp_path / "ranked_trials.json").read_text())["Run"] == run
+
+
+def test_match_signature_tracks_assessment_controls():
+ from trialmatchai.orchestration import _match_signature
+
+ assert _match_signature({}) != _match_signature({"rag": {"enabled": False}})
+ assert _match_signature({}) != _match_signature({"use_cot_reasoning": False})
+ assert _match_signature({}) != _match_signature({"rag": {"max_trials_rag": 5}})
+ assert assessment_settings({})["enabled"] is True
+
+
+def test_shortlist_budget_change_invalidates_resume(pipeline):
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ assert main.main_pipeline(config=config) == 0
+ config["rag"]["max_trials_rag"] = 1
+ assert not match_controls_current(output / "ranked_trials.json", config)
+ assert count_pending(config) == (1, 0)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, False]
+ assert json.loads((output / "ranked_trials.json").read_text())["Run"]["assessment"]["max_trials_rag"] == 1
+
+
+@pytest.mark.parametrize("narrative", [[], [" ", "\n"]])
+def test_aborted_assessment_cannot_reuse_prior_verdicts(pipeline, narrative):
+ from trialmatchai.interop.exporters.html_report import profile_to_model
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ assert main.main_pipeline(config=config) == 0
+ config["use_cot_reasoning"] = True
+ summary = main._load_patient_inputs(config)[0][1]
+ original_narrative = summary["patient_narrative"]
+ summary["patient_narrative"] = narrative
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False]
+ payload = json.loads((output / "ranked_trials.json").read_text())
+ assert payload["RankedTrials"] == [{"TrialID": "NCT1", "Score": 0.7}]
+ assert payload["Run"]["assessment_status"] == "unavailable"
+ assert payload["Run"]["assessed_trial_ids"] == []
+ assert (output / "NCT1.json").exists()
+ assert not profile_to_model(output)["trials"][0]["reasoning_available"]
+ assert count_pending(config) == (1, 0)
+ summary["patient_narrative"] = original_narrative
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, True]
+ assert count_pending(config) == (0, 1)
+
+
+def test_failed_forced_write_cannot_revive_old_output(pipeline, monkeypatch):
+ from trialmatchai.matching import eligibility_base
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ assert main.main_pipeline(config=config) == 0
+ previous = (output / "NCT1.json").read_bytes()
+ config["use_cot_reasoning"] = True
+
+ def fail_write(*args, **kwargs):
+ raise OSError("simulated write failure")
+
+ with monkeypatch.context() as patch:
+ patch.setattr(eligibility_base, "write_json_file", fail_write)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ payload = json.loads((output / "ranked_trials.json").read_text())
+ assert payload["Run"]["assessment_status"] == "unavailable"
+ assert payload["RankedTrials"] == [{"TrialID": "NCT1", "Score": 0.7}]
+ assert (output / "NCT1.json").read_bytes() == previous
+ assert count_pending(config) == (1, 0)
+ assert not list(output.glob(".assessment-*"))
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, True, True]
+ assert count_pending(config) == (0, 1)
+
+
+@pytest.mark.parametrize("response", ['{"error": "transient"}', '{}', 'not JSON'])
+def test_unavailable_assessments_are_retried(pipeline, monkeypatch, response):
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ save = BaseTrialProcessor._save_outputs
+ with monkeypatch.context() as patch:
+ patch.setattr(BaseTrialProcessor, "_save_outputs", lambda self, tid, text, folder: save(self, tid, response, folder))
+ assert main.main_pipeline(config=config) == 0
+ assert match_controls_current(output / "ranked_trials.json", config)
+ assert not match_is_complete(output / "ranked_trials.json", config)
+ assert count_pending(config) == (1, 0)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, False]
+ assert count_pending(config) == (0, 1)
+
+
+def test_partial_assessment_retries_only_missing_trial(pipeline, monkeypatch):
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ write_json_file({"eligibility_criteria": "Adults"}, str(Path(config["paths"]["trials_json_folder"]) / "NCT2.json"))
+
+ def second(*args):
+ path = str(Path(args[0]) / "top_trials.txt")
+ write_text_file(["NCT1", "NCT2"], path)
+ return [("NCT1", 0.7), ("NCT2", 0.6)], path, {"NCT1": 0.7, "NCT2": 0.6}
+
+ monkeypatch.setattr(main, "run_second_level_search", second)
+ save = BaseTrialProcessor._save_outputs
+ generated = []
+
+ def save_with_failure(self, tid, text, folder):
+ generated.append(tid)
+ if tid == "NCT2" and generated.count(tid) == 1:
+ text = '{"error": "transient"}'
+ save(self, tid, text, folder)
+
+ monkeypatch.setattr(BaseTrialProcessor, "_save_outputs", save_with_failure)
+ assert main.main_pipeline(config=config) == 0
+ assert json.loads((output / "ranked_trials.json").read_text())["Run"]["assessment_status"] == "partial"
+ completed_mtime = (output / "NCT1.json").stat().st_mtime_ns
+ assert count_pending(config) == (1, 0)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert generated.count("NCT1") == 1 and generated.count("NCT2") == 2
+ assert (output / "NCT1.json").stat().st_mtime_ns == completed_mtime
+ assert count_pending(config) == (0, 1)
+
+
+def test_deleted_assessment_is_pending_and_recomputed(pipeline):
+ from trialmatchai.orchestration import count_pending
+
+ main, config, calls, output = pipeline
+ assert main.main_pipeline(config=config) == 0
+ (output / "NCT1.json").unlink()
+ assert count_pending(config) == (1, 0)
+ assert main.main_pipeline(config=config, resume=True) == 0
+ assert calls == [False, False]
+ assert count_pending(config) == (0, 1)
+
+
+def test_report_marks_partial_assessment_and_ignores_unassociated_outputs():
+ from trialmatchai.interop.exporters.html_report import build_report_model
+
+ data = {"TrialID": "NCT1", "Final Decision": "Eligible"}
+ run = assessment_run_info({}, [data], {"NCT1", "NCT2"})
+ model = build_report_model(
+ patient_summary={}, ranked={"RankedTrials": [{"TrialID": "NCT1"}, {"TrialID": "NCT2"}], "Run": run},
+ eligibility_by_id={"NCT1": data, "NCT2": {"Final Decision": "Eligible"}},
+ meta_by_id={}, cot_by_id={"NCT2": "stale text"}, generated_at="x",
+ )
+ assert model["run"]["assessment_status"] == "partial"
+ assert model["trials"][0]["reasoning_available"]
+ assert not model["trials"][1]["reasoning_available"]
+ assert model["trials"][1]["final_decision"] is None
+ assert model["trials"][1]["cot"] is None
+
+
+def test_report_downgrades_availability_when_saved_assessment_is_missing():
+ from trialmatchai.interop.exporters.html_report import build_report_model
+
+ run = assessment_run_info({}, [{"TrialID": "NCT1", "Final Decision": "Eligible"}], {"NCT1"})
+ model = build_report_model(
+ patient_summary={}, ranked={"RankedTrials": [{"TrialID": "NCT1"}], "Run": run},
+ eligibility_by_id={}, meta_by_id={}, generated_at="x",
+ )
+ assert model["run"]["mode"] == "retrieval_only"
+ assert model["run"]["assessment_status"] == "unavailable"
diff --git a/tests/test_audit_fixes_batch8.py b/tests/test_audit_fixes_batch8.py
index 650d7a83..9d9a3ce7 100644
--- a/tests/test_audit_fixes_batch8.py
+++ b/tests/test_audit_fixes_batch8.py
@@ -389,7 +389,10 @@ def test_resume_all_pending_fail_returns_nonzero(tmp_path, monkeypatch):
done = PatientProfile.model_validate({"patient_id": "pdone", "demographics": {}})
out = tmp_path / "results" / "pdone"
out.mkdir(parents=True)
- (out / "ranked_trials.json").write_text("[]", encoding="utf-8") # valid marker -> skipped
+ from trialmatchai.matching.assessment import assessment_run_info
+ (out / "ranked_trials.json").write_text(json.dumps({
+ "RankedTrials": [], "Run": assessment_run_info({"rag": {"enabled": False}, "use_cot_reasoning": False}, [], set()),
+ }), encoding="utf-8") # Valid current marker -> skipped.
def _boom_first_level(*a, **k):
raise RuntimeError("forced failure")
@@ -408,7 +411,10 @@ def test_first_level_none_counted_as_failed_on_resume(tmp_path, monkeypatch):
done = PatientProfile.model_validate({"patient_id": "pdone2", "demographics": {}})
out = tmp_path / "results" / "pdone2"
out.mkdir(parents=True)
- (out / "ranked_trials.json").write_text("[]", encoding="utf-8")
+ from trialmatchai.matching.assessment import assessment_run_info
+ (out / "ranked_trials.json").write_text(json.dumps({
+ "RankedTrials": [], "Run": assessment_run_info({"rag": {"enabled": False}, "use_cot_reasoning": False}, [], set()),
+ }), encoding="utf-8")
main_module = _setup_pipeline(
monkeypatch, tmp_path,
diff --git a/tests/test_resume_and_atomicity.py b/tests/test_resume_and_atomicity.py
index 127babbe..738c31eb 100644
--- a/tests/test_resume_and_atomicity.py
+++ b/tests/test_resume_and_atomicity.py
@@ -237,7 +237,10 @@ def test_count_pending_uses_valid_ranked_marker(tmp_path):
for pid in ("P1", "P2", "P3"):
(profiles / f"{pid}.json").write_text("{}", encoding="utf-8")
(out / "P1").mkdir(parents=True)
- (out / "P1" / "ranked_trials.json").write_text("[]", encoding="utf-8") # done
+ from trialmatchai.matching.assessment import assessment_run_info
+ (out / "P1" / "ranked_trials.json").write_text(json.dumps({
+ "RankedTrials": [], "Run": assessment_run_info({}, [], set()),
+ }), encoding="utf-8") # Current, valid empty result.
(out / "P2").mkdir(parents=True)
(out / "P2" / "ranked_trials.json").write_text("[bad", encoding="utf-8") # corrupt -> pending
# P3 has no ranked file -> pending
@@ -255,7 +258,10 @@ def test_run_matching_skips_model_when_all_done(tmp_path, monkeypatch):
out = tmp_path / "out"
(profiles / "P1.json").write_text("{}", encoding="utf-8")
(out / "P1").mkdir(parents=True)
- (out / "P1" / "ranked_trials.json").write_text("[]", encoding="utf-8")
+ from trialmatchai.matching.assessment import assessment_run_info
+ (out / "P1" / "ranked_trials.json").write_text(json.dumps({
+ "RankedTrials": [], "Run": assessment_run_info({}, [], set()),
+ }), encoding="utf-8")
config = {"patient_inputs": {"profile_dir": str(profiles)}, "paths": {"output_dir": str(out)}}
monkeypatch.setattr(main_mod, "main_pipeline", _boom) # must not be called
 +